Deterministic Simulation Testing
Distributed systems are hard to test because partial failures overlap with live traffic and the same fault can produce different execution traces on different runs. Deterministic simulation testing addresses this by replacing real clocks, networks, and storage with simulated components driven by a single-threaded execution loop. This allows simulating both hard failures and routine slowdowns—such as network and disk latency spikes—and more importantly makes every execution reproducible. This article explains the technique using a quorum key-value store as a running example, with code from Tickloom, a Java implementation of the approach.
17 November 2026
Unmesh is a Distinguished Engineer at Thoughtworks, based in Pune, India. He is the author of Patterns of Distributed Systems.
Distributed systems are notoriously hard to test. It is common to hear stories of subtle bugs surfacing in well-architected, heavily tested systems that have been running reliably in production for years. The Jepsen testing suite, for instance, routinely exposes critical consistency violations and split-brain scenarios in established, battle-tested databases.
If we have robust CI/CD pipelines, extensive test coverage, and strict code reviews, why is it so difficult to catch these bugs before they hit production? The answer lies in the fundamental mismatch between how we test software and the reality of the environments in which distributed systems operate.
Limitations of Standard Testing Mechanisms
Unit tests validate local logic in isolation. Integration tests validate interactions between components. But neither proves what clients observe when part of the system fails while requests are in flight. End-to-end scenarios test the system with all components integrated, but the focus is mostly on verifying functionality and sticking to the happy path. When standard integration tests do simulate failures, they usually test clean, anticipated scenarios—like gracefully shutting down a database node. But in a distributed architecture, the hardest bugs do not live inside the isolated components; they live in the unpredictable interactions between the components and the infrastructure where partial failures and live traffic overlap.
Gray Failures
When the systems are distributed, our assumptions about perfect environments collapse. As the classic “Fallacies of Distributed Computing” warn us, the network is not reliable, latency is never zero, and topology constantly changes. Distributed systems suffer from partial failures. One part of the system crashes or hangs while the rest of the system keeps running, leading to conflicting views of the cluster state.
In production, components rarely fail cleanly. A node doesn't just cleanly disconnect; it operates erratically, introducing subtle anomalies. The network doesn't cleanly partition into two isolated halves. Instead, it suffers from asymmetric routing, selectively drops a small percentage of packets, or delays specific messages just long enough to trigger a timeout on one node but not another. A process does not necessarily crash. Instead, it experiences a Stop-The-World Garbage Collection pause on the JVM, or CPU throttling. The pause lasts just long enough to cause bad message interleavings, causing the node to miss a consensus heartbeat, only for it to wake up seconds later completely unaware that it was ever paused. A disk does not fail completely. Instead, it experiences a localized latency spike—taking 500ms instead of 2ms to sync a Write-Ahead Log (WAL)—or it silently corrupts a few sectors without causing a complete hardware failure.
These gray failures create the exact interleavings of events that cause robust systems to break. Standard testing simply cannot create these highly specific, degraded conditions on demand.
To force these hard to find failure modes to surface, the common technique used is to inject faults into running systems intentionally.
From Chaos Engineering to Correctness Checking
Chaos engineering tests whether a system stays available under fault. It introduces disruptions—like terminating pods or disrupting network traffic—while monitoring infrastructure health. Consider a three-node key-value store—Athens, Byzantium, and Cyrene—where reads and writes require a majority of two replicas. If we kill a node during a quorum write, the primary question chaos engineering asks is: does the write still succeed and does the cluster recover?
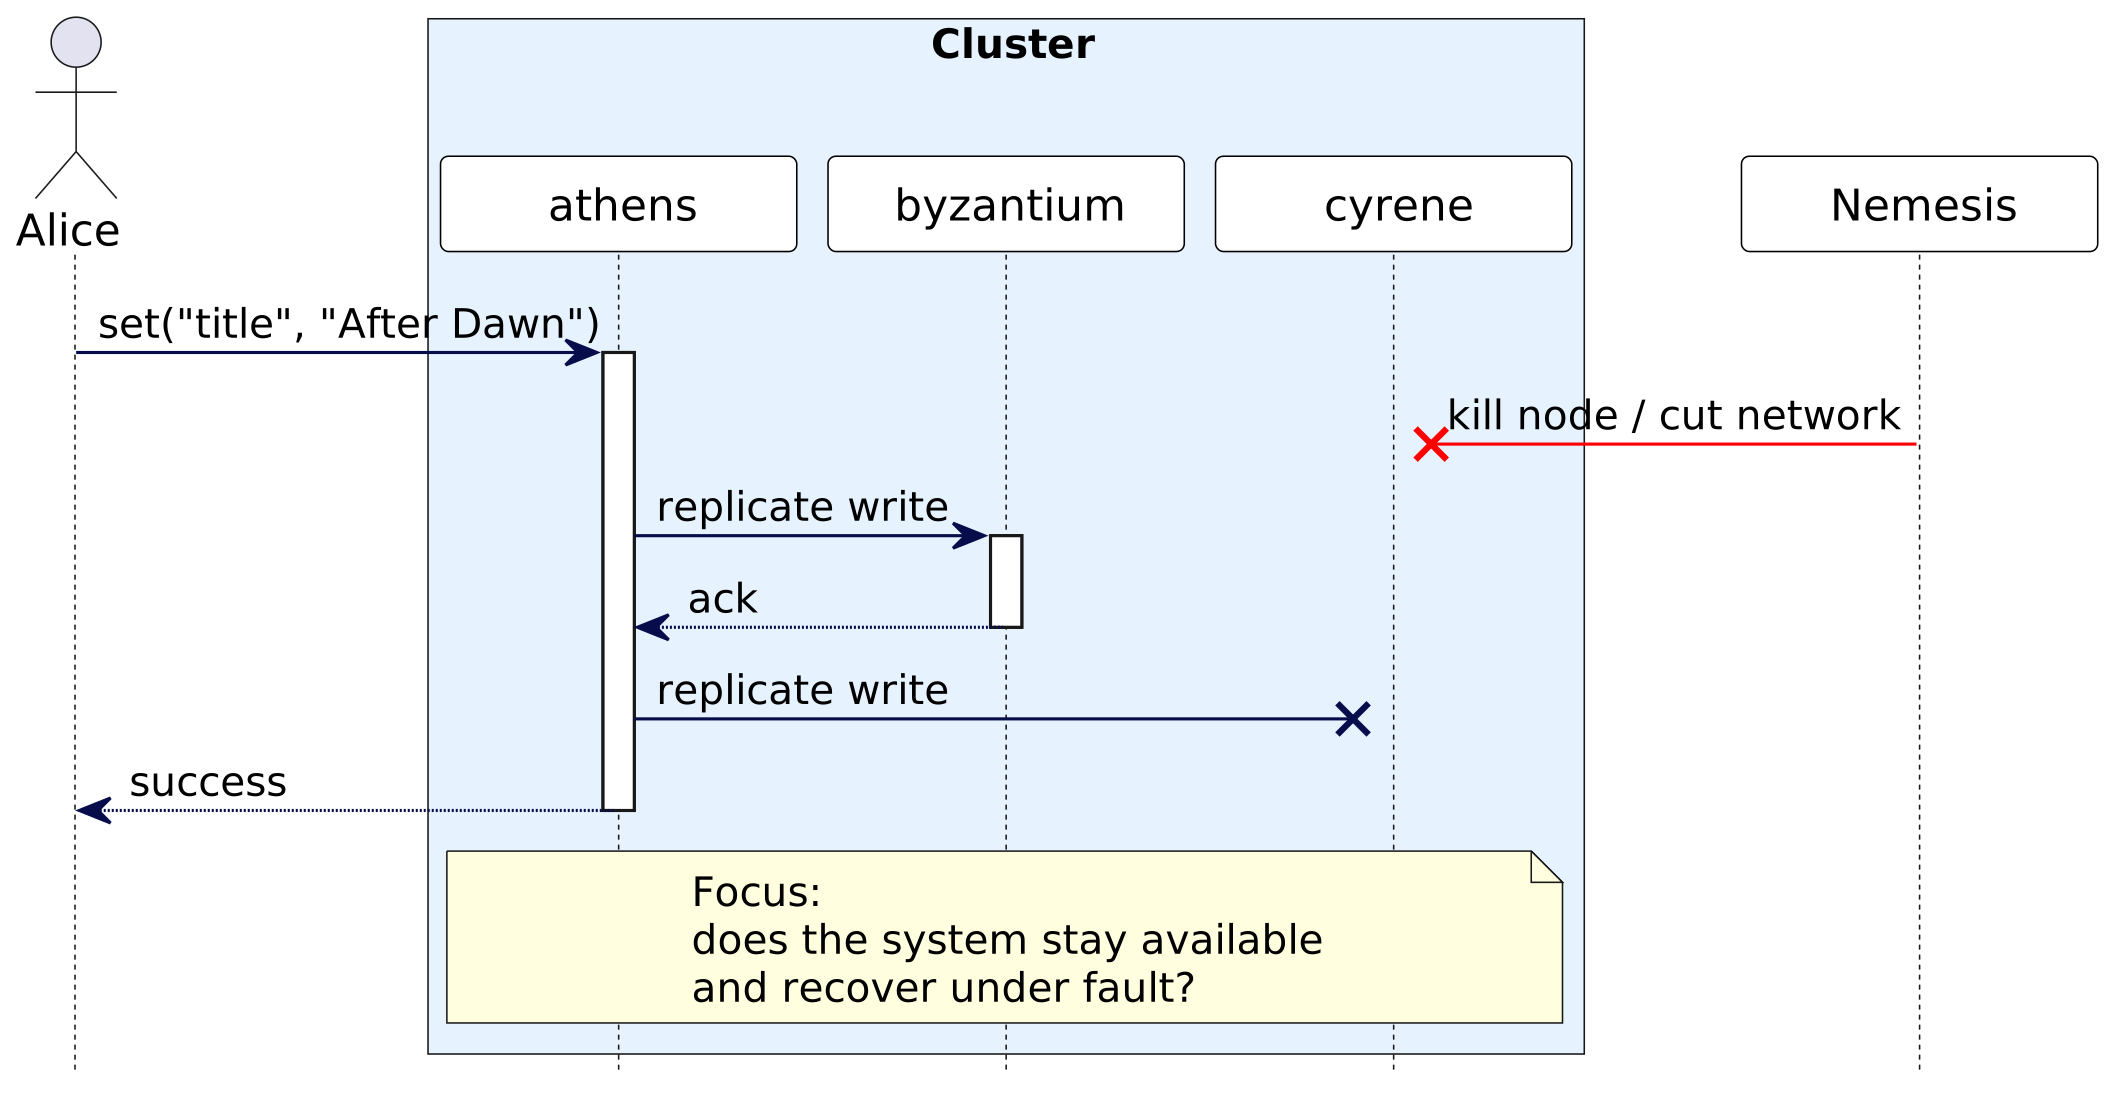
Figure 1: Chaos engineering focuses on resilience: does the system stay available when a node is killed?
But availability is not the same as correctness. A system can restart pods, keep serving traffic, and stay within latency limits while still violating the semantics the client depends on. Returning a successful response with stale or corrupted data means the system is technically available, yet incorrect from the user's perspective. Suppose a network partition isolates Cyrene while Alice writes a new value. Athens and Byzantium form a majority, so the write succeeds, leaving Cyrene on the old value:
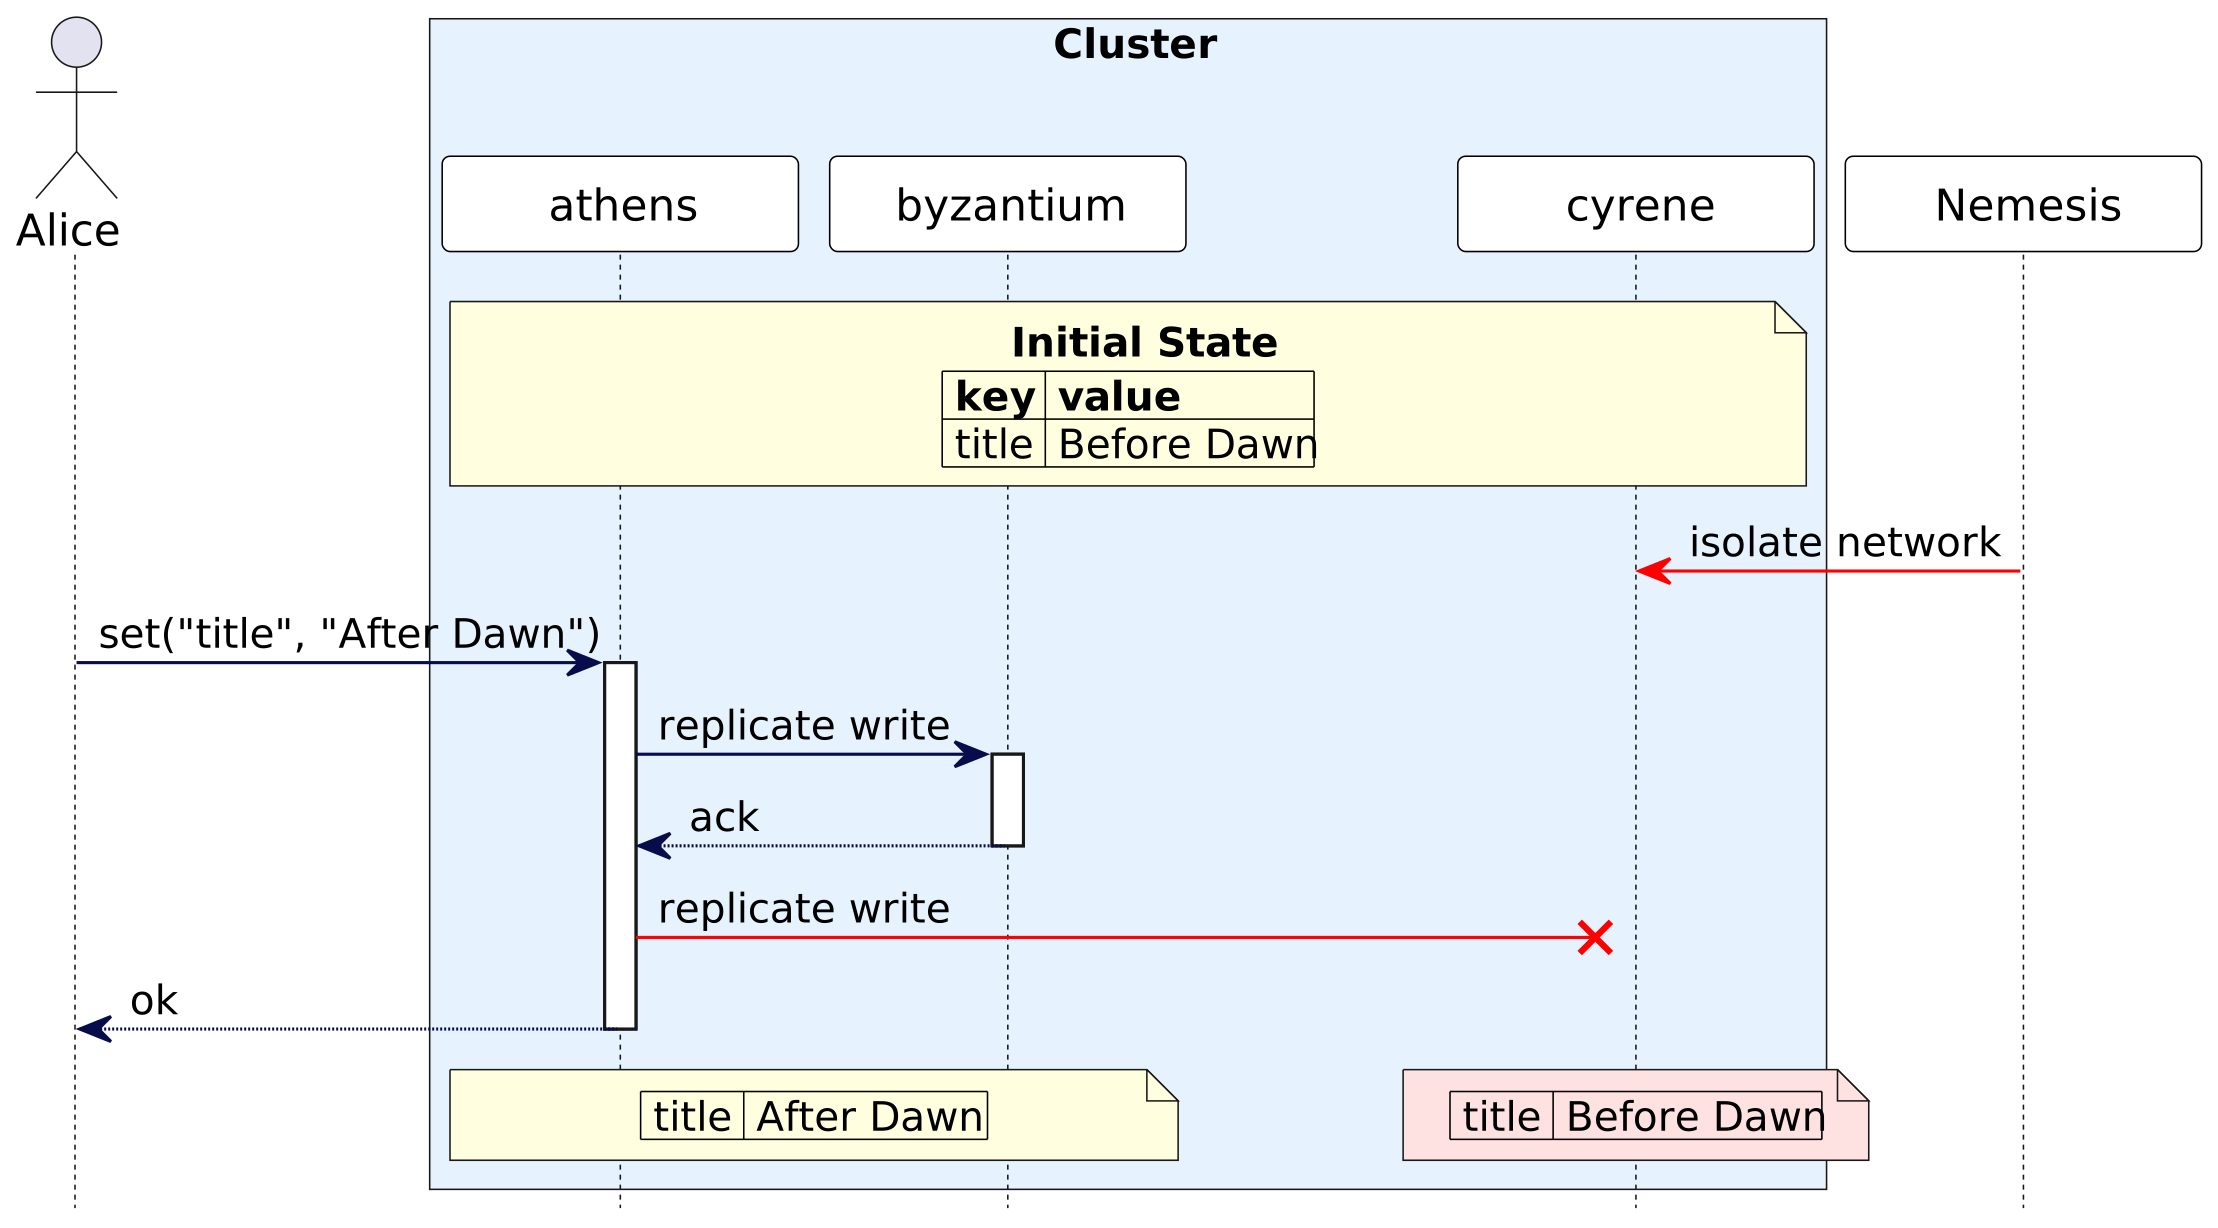
Figure 2: A quorum write succeeds on Athens and Byzantium while a network partition leaves Cyrene holding the older value.
If Bob then reads from Cyrene, and it reads from its local state instead of performing a quorum read, Bob receives the older value even though Alice's write already succeeded. Every request returned a response, so the system stayed available, yet its consistency guarantee was broken:
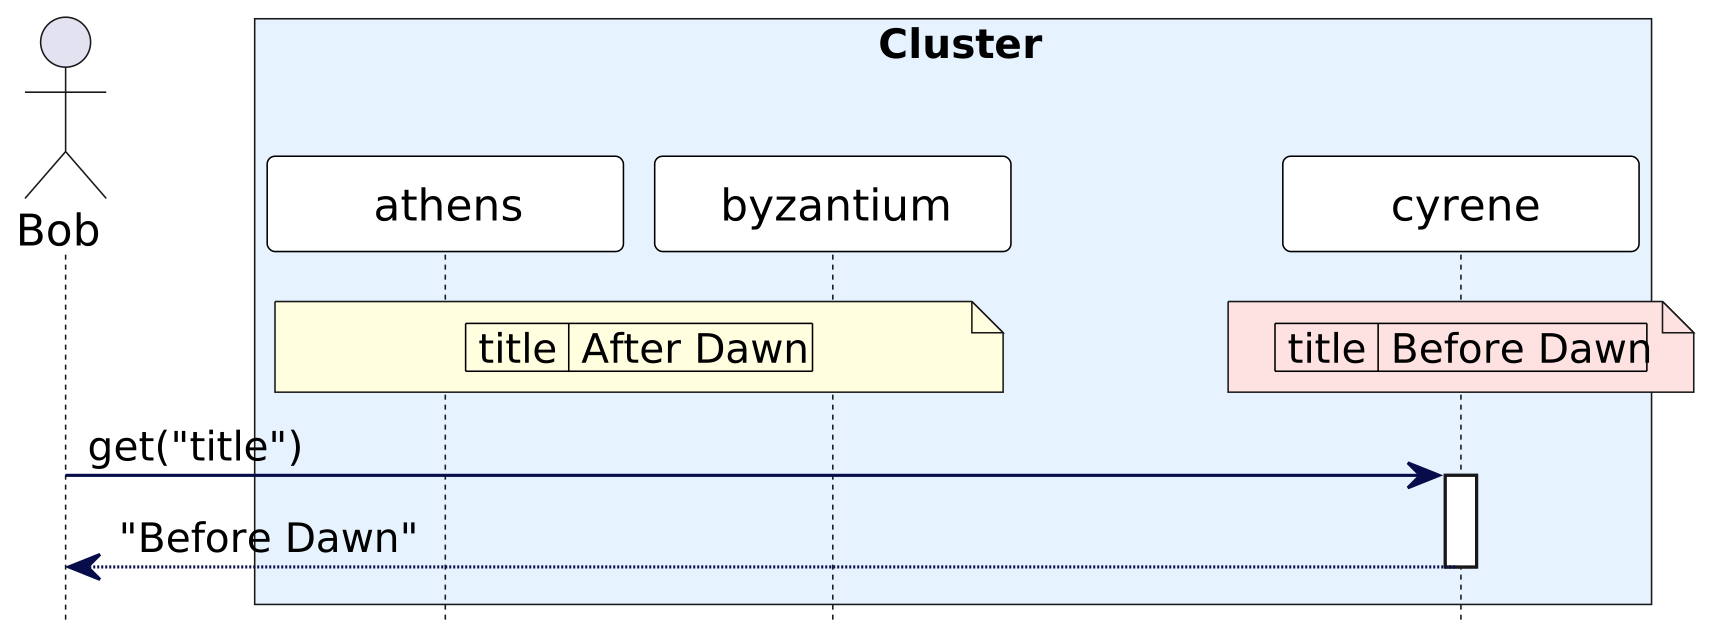
Figure 3: Bob reads from Cyrene and receives the stale value “Before Dawn” even though Alice's write of “After Dawn” already succeeded.
Jepsen catches this by focusing strictly on correctness from the client's perspective. It runs a live system, injects faults, records the client-visible history of operations, and checks whether that history is consistent with the system's claimed semantics:
Alice: invoke set("title", "After Dawn")
Alice: ok     set("title", "After Dawn")
Bob:   invoke get("title")
Bob:   ok     get("title") -> "Before Dawn"   // violation: stale read after acknowledged write
This is the reason for faulting a live system. It allows inspecting what happens to real client operations while the system has failures.
The Nondeterminism Problem
Chaos testing and frameworks like Jepsen are effective at finding bugs, but finding a bug is only half the work. To fix a bug, you first need to reproduce it. This is where live testing hits a wall. Reproducing a failure in a live cluster fails on two separate levels:
- Unseeded fault schedules: Faults are introduced randomly to mimic unpredictable production conditions—dropping packets, crashing nodes, or injecting delays. If this randomness is unseeded (or reseeded with the current system time), every test run generates a completely different sequence of faults at different times. A bug encountered on one run cannot be reproduced simply because the test harness cannot regenerate that schedule. We can fix this to some extent by using a seeded pseudo-random number generator, ensuring that rerunning with the same seed produces the exact same sequence of fault decisions.
- Execution nondeterminism: Even with the exact same sequence of faults, the system is still not guaranteed to produce the same execution. In a live environment, the application does not advance in lockstep with the fault generator. The software runs against physical wall-clock time, asynchronous OS thread scheduling, and real network and disk buffers. A microscopic timing shift—a garbage collection pause, a thread context switch, or a delayed TCP ACK—changes which messages are in flight at the exact millisecond a fault hits.
Consider a quorum write where one replica (Cyrene) is isolated by a network fault. Athens, the coordinator, needs two of three replicas: its own write and one acknowledgment. In Run 1, Byzantium's acknowledgment arrives early, Athens forms a quorum, and Alice gets a success. In Run 2, with the exact same fault injected, Byzantium's acknowledgment is delayed in transit. Athens times out and returns a failure to Alice, and the acknowledgment arrives only after the timeout has expired.
Neither outcome is wrong. But they are different executions of the same test, and nothing in the test decides which one we get. If a bug lived only on the Run 2 path, rerunning the test might land on Run 1 every time, missing the bug.
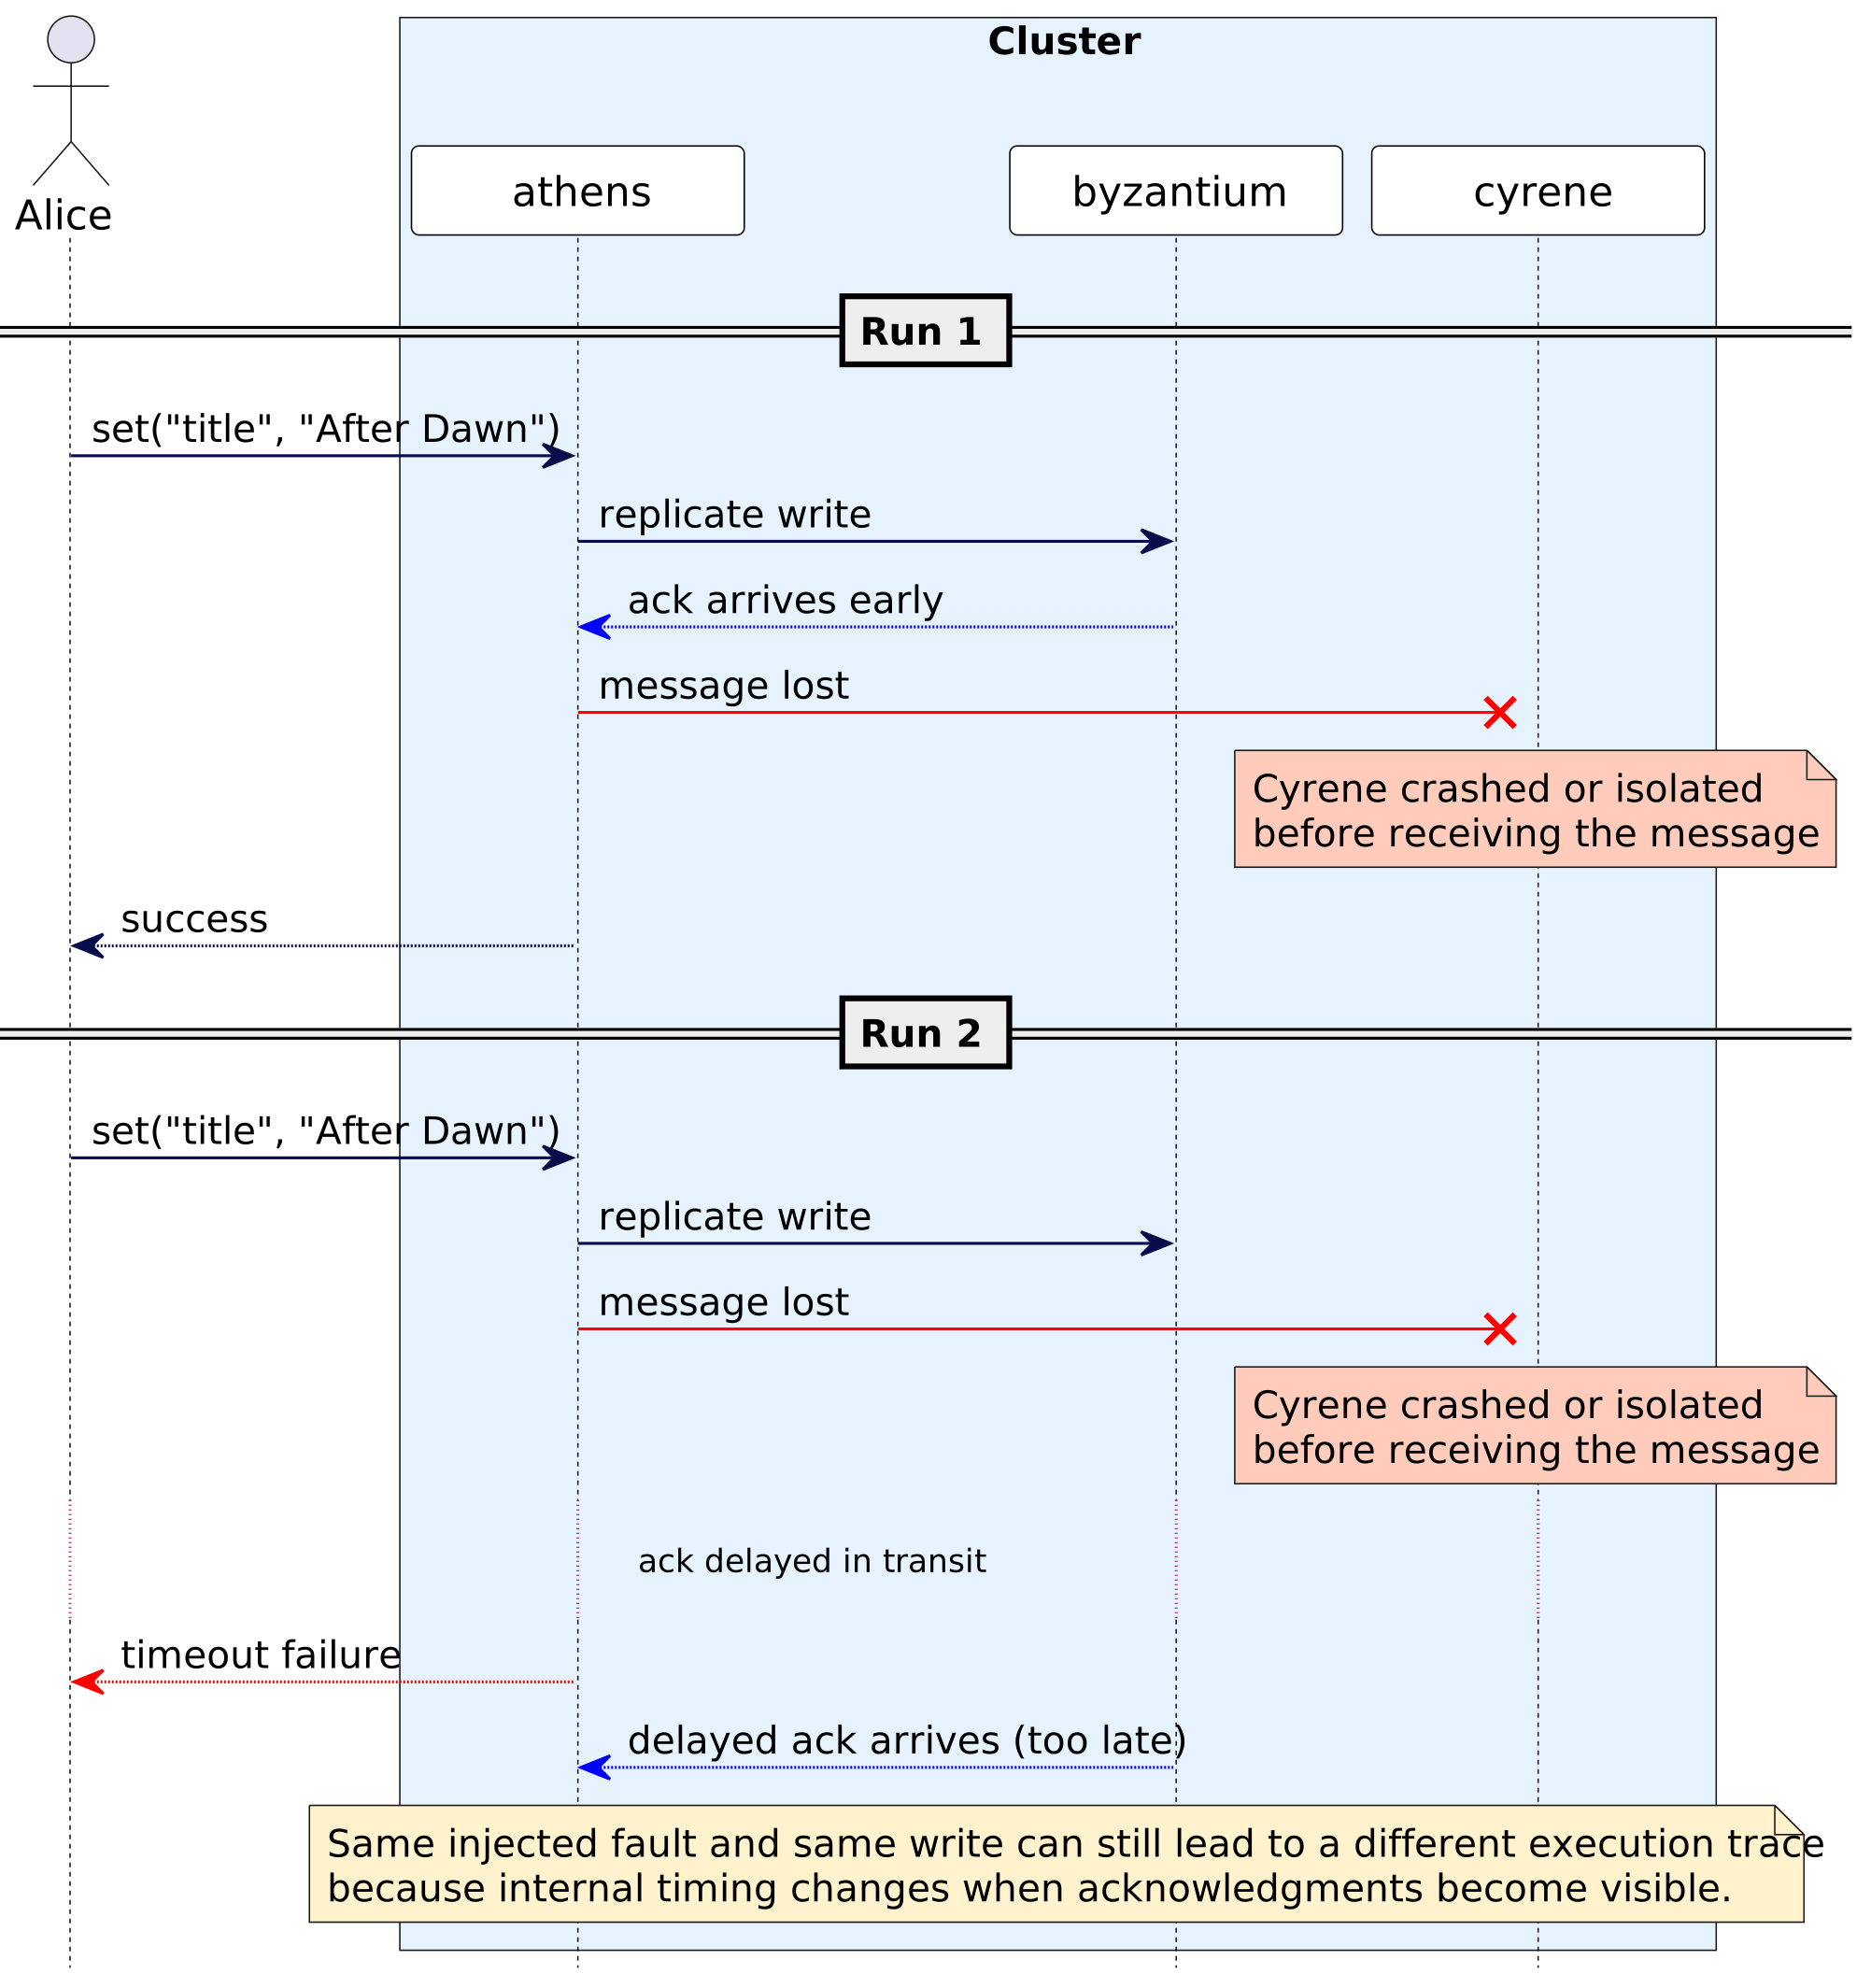
Figure 4: Two runs with the same injected fault (Cyrene isolated) produce different execution traces: in Run 1 the acknowledgment arrives in time, while in Run 2 the coordinator times out before the delayed acknowledgment arrives.
Sources of Nondeterminism
There are four major sources of nondeterminism in a distributed system: the system clock, thread scheduling, network timing, and disk timing. Each changes when events become visible to the software, producing different execution interleavings on different runs.
Clock and Time
Every timeout, retry and timestamp is a comparison against a clock. In a live system, the time between two events depends on everything else the machine is doing — a GC pause, a busy core, a slow network hop — so the same operation can take 40ms in one run and 120ms in the next. Wall clocks can also jump when NTP corrects them. In the figure, the same write finishes inside the timeout window in Run 1 and crosses it in Run 2. The code made the same decision both times; the clock gave it a different answer. To repeat a run, the test has to control what the clock reads.
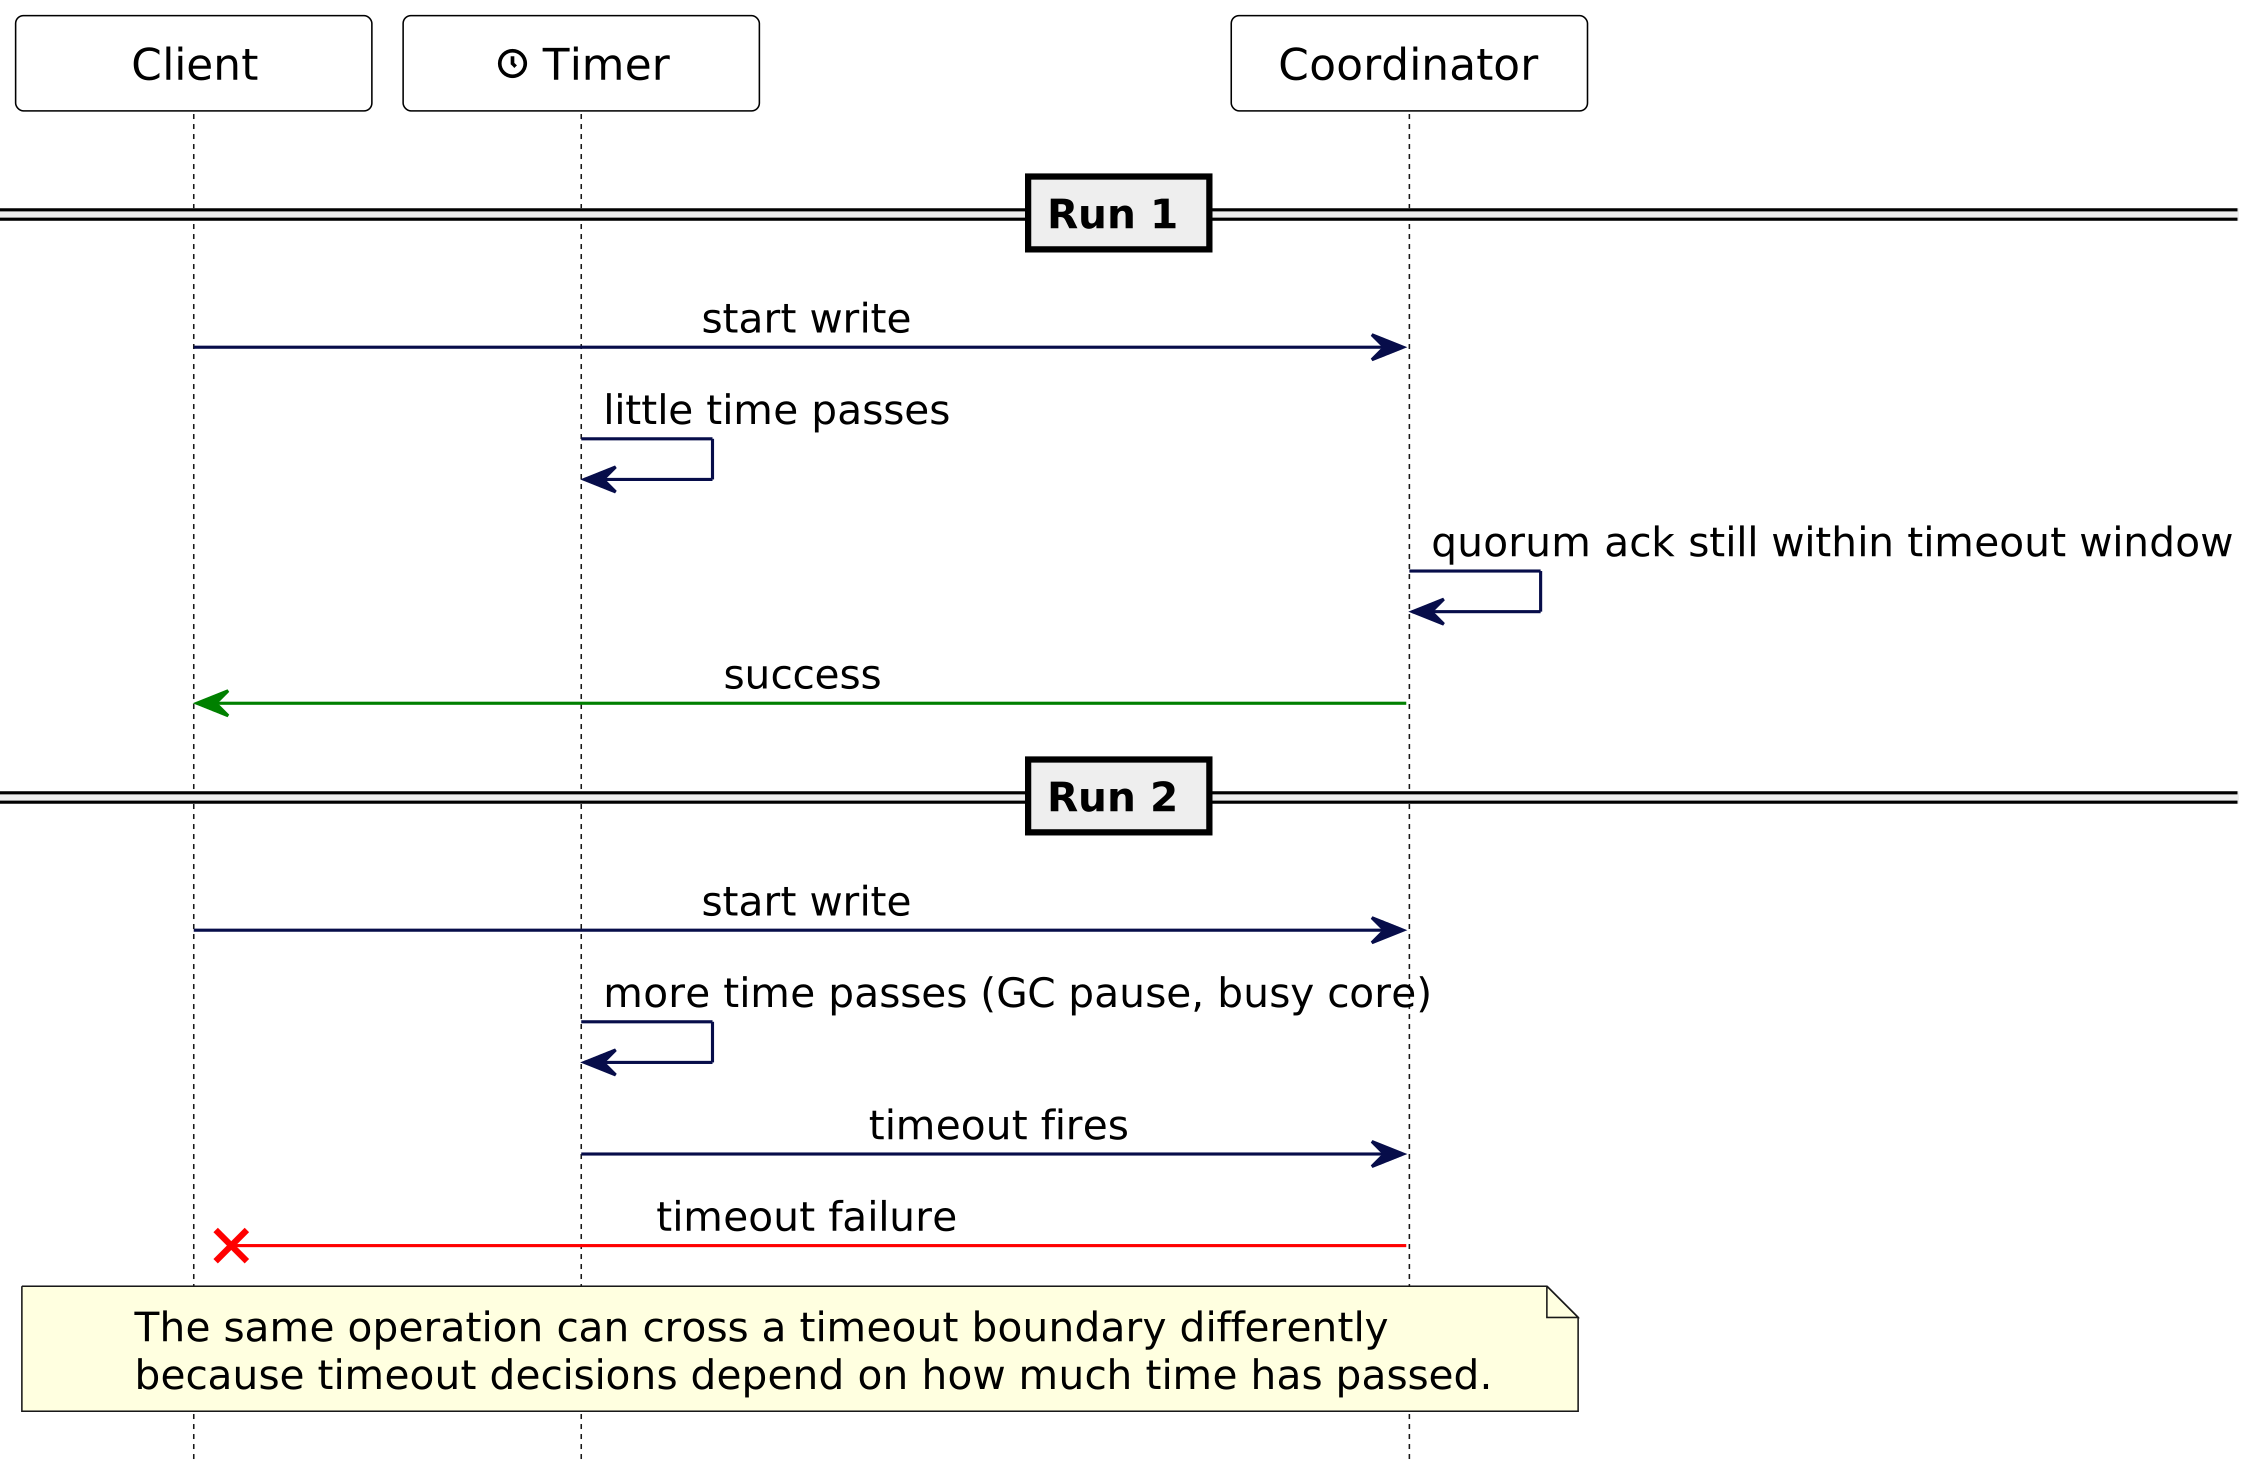
Figure 5: The same write operation can succeed or time out depending on how much time passes before the acknowledgment arrives.
Thread Scheduling
Within one process, the operating system decides which thread runs next, and that decision changes with load, core count and what else is running. Across a cluster it is worse: each process runs at its own speed, and a process paused by GC falls behind the others. In the figure, Alice's write and Bob's read arrive at the same replica. In Run 1 the write handler runs first and Bob sees the new value; in Run 2 the read handler runs first and Bob sees the old one. To repeat a run, the test has to decide which work runs next.
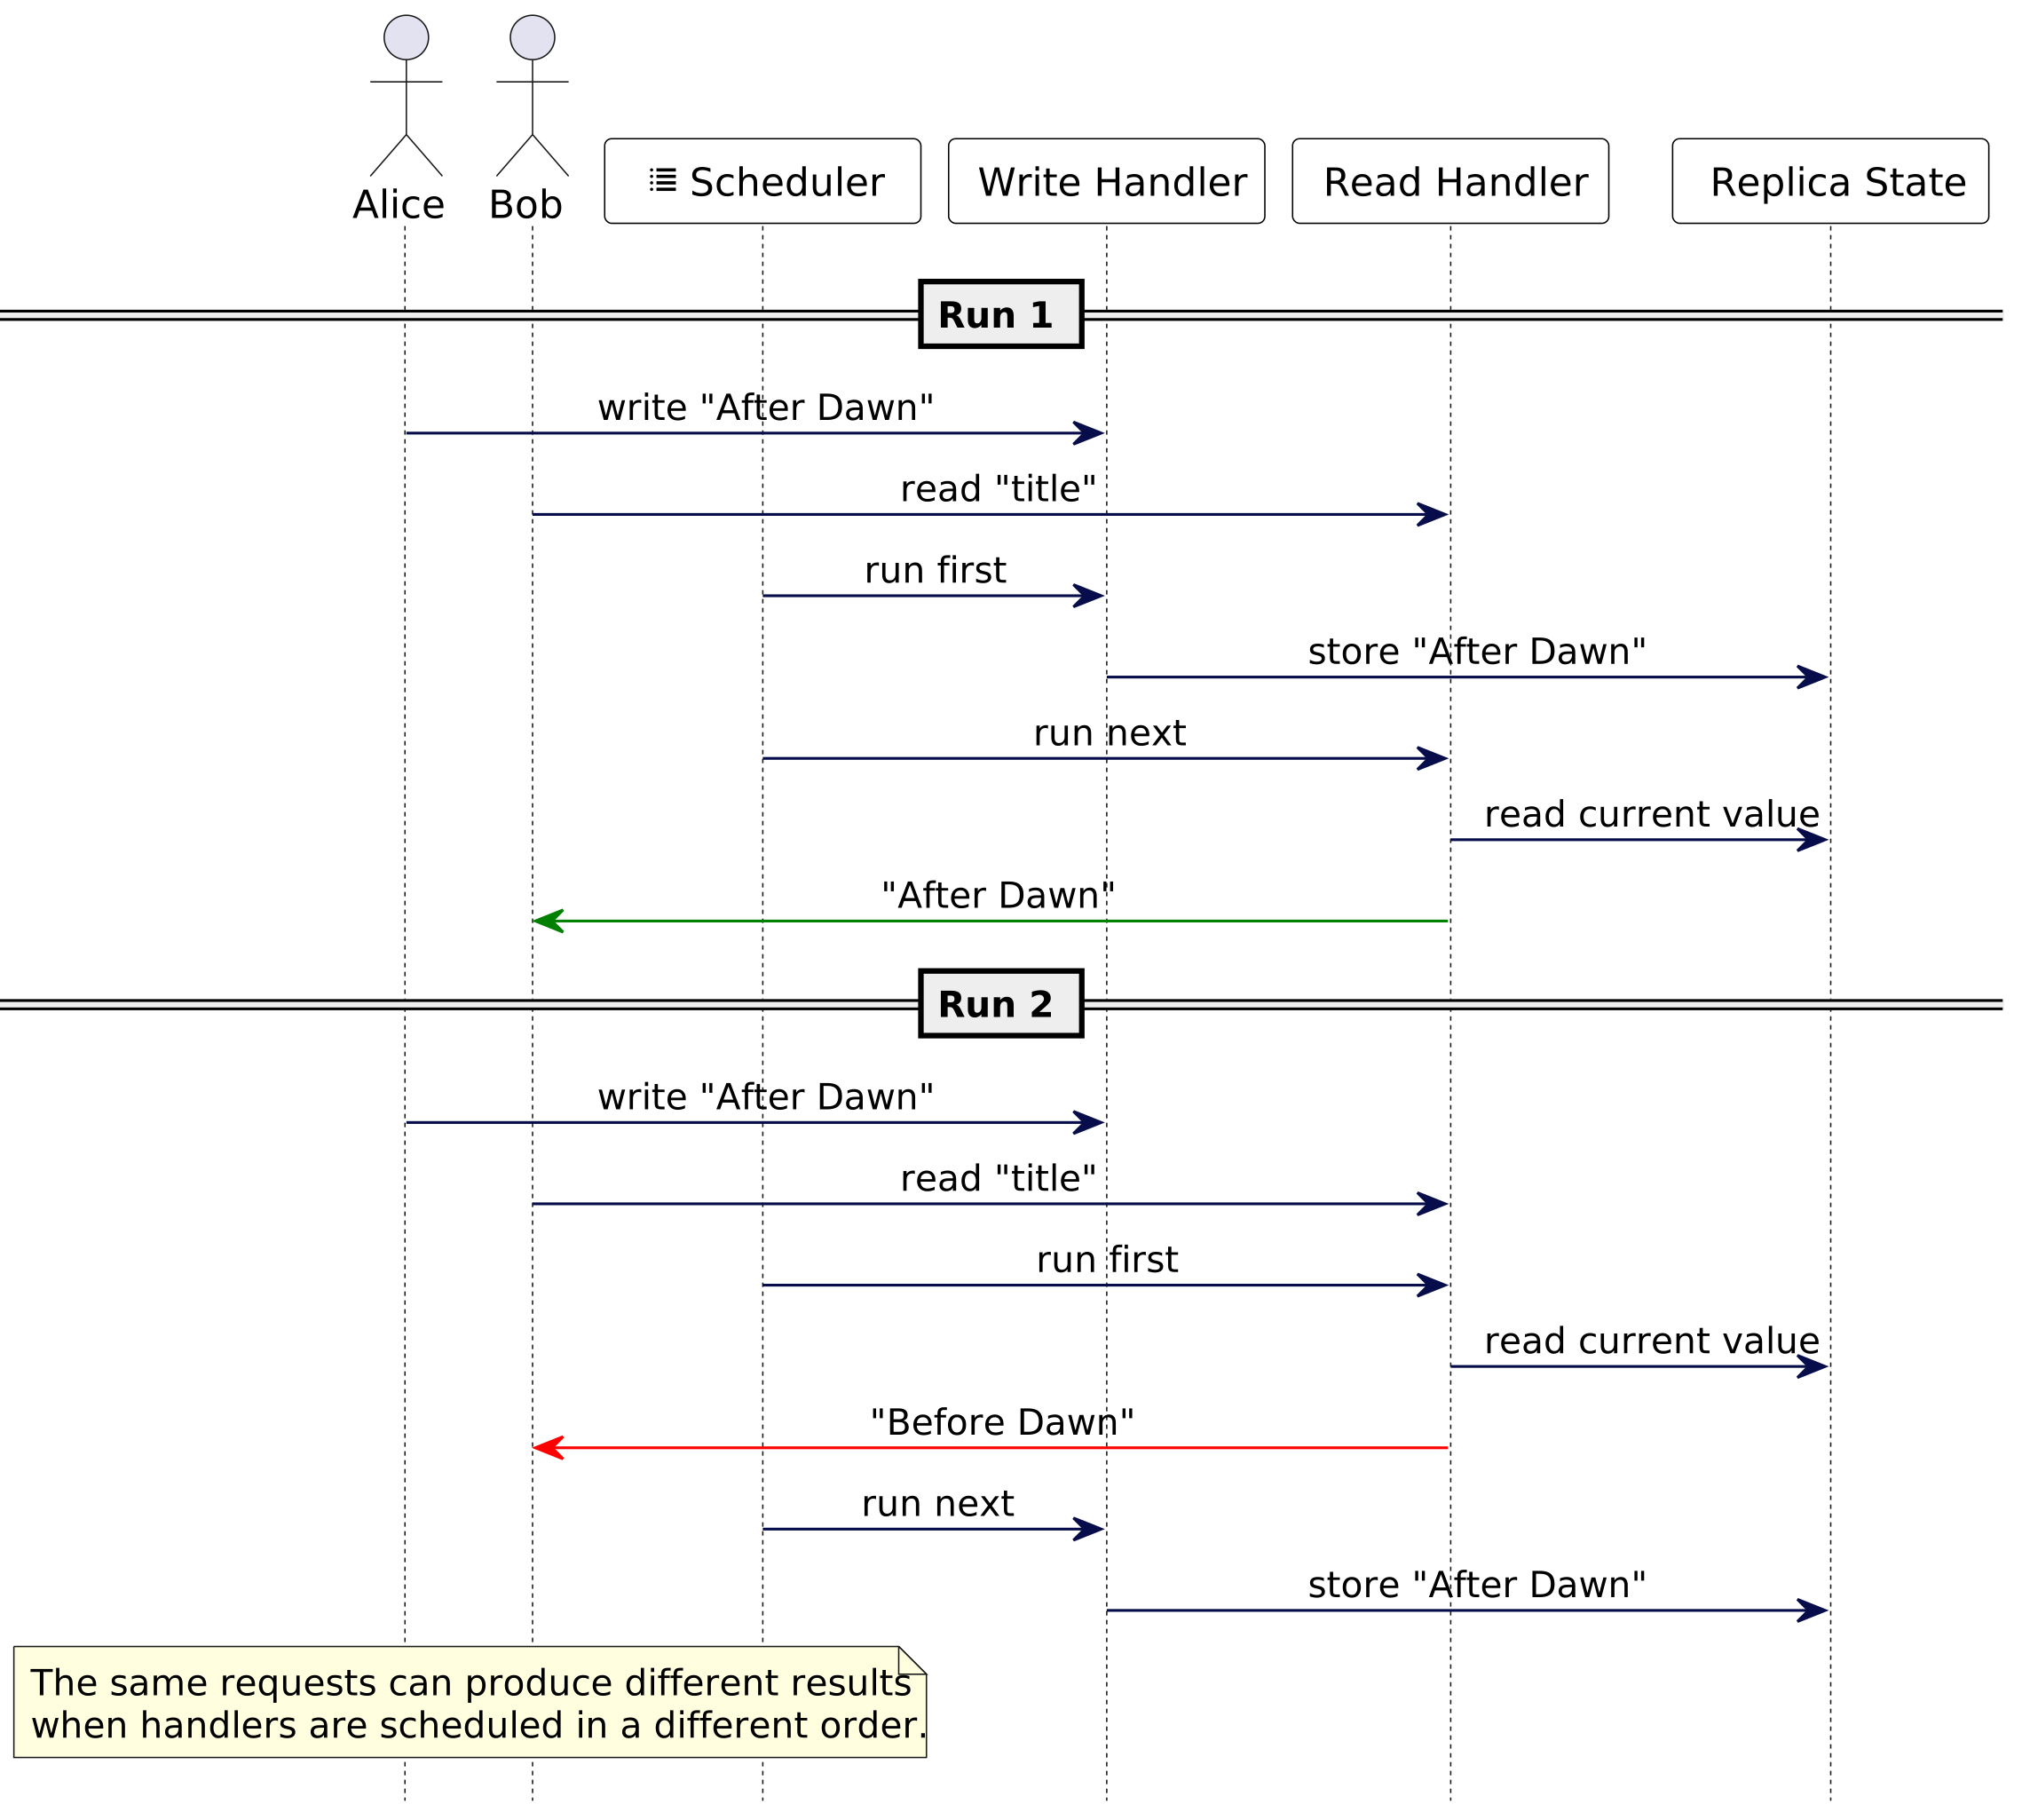
Figure 6: Different thread scheduling orders produce different values for the same read operation.
Network Timing
A message's delivery time depends on buffering, congestion, retransmission and routing, none of which the program sees. Two messages sent in one order can arrive in the other. In the figure, the same replication message reaches the replica before Bob's read in Run 1 and after it in Run 2, so Bob gets different values. Injecting the same partition or loss rate does not fix this, because the timing of every message that survives still varies. To repeat a run, the test has to decide when each message is delivered.
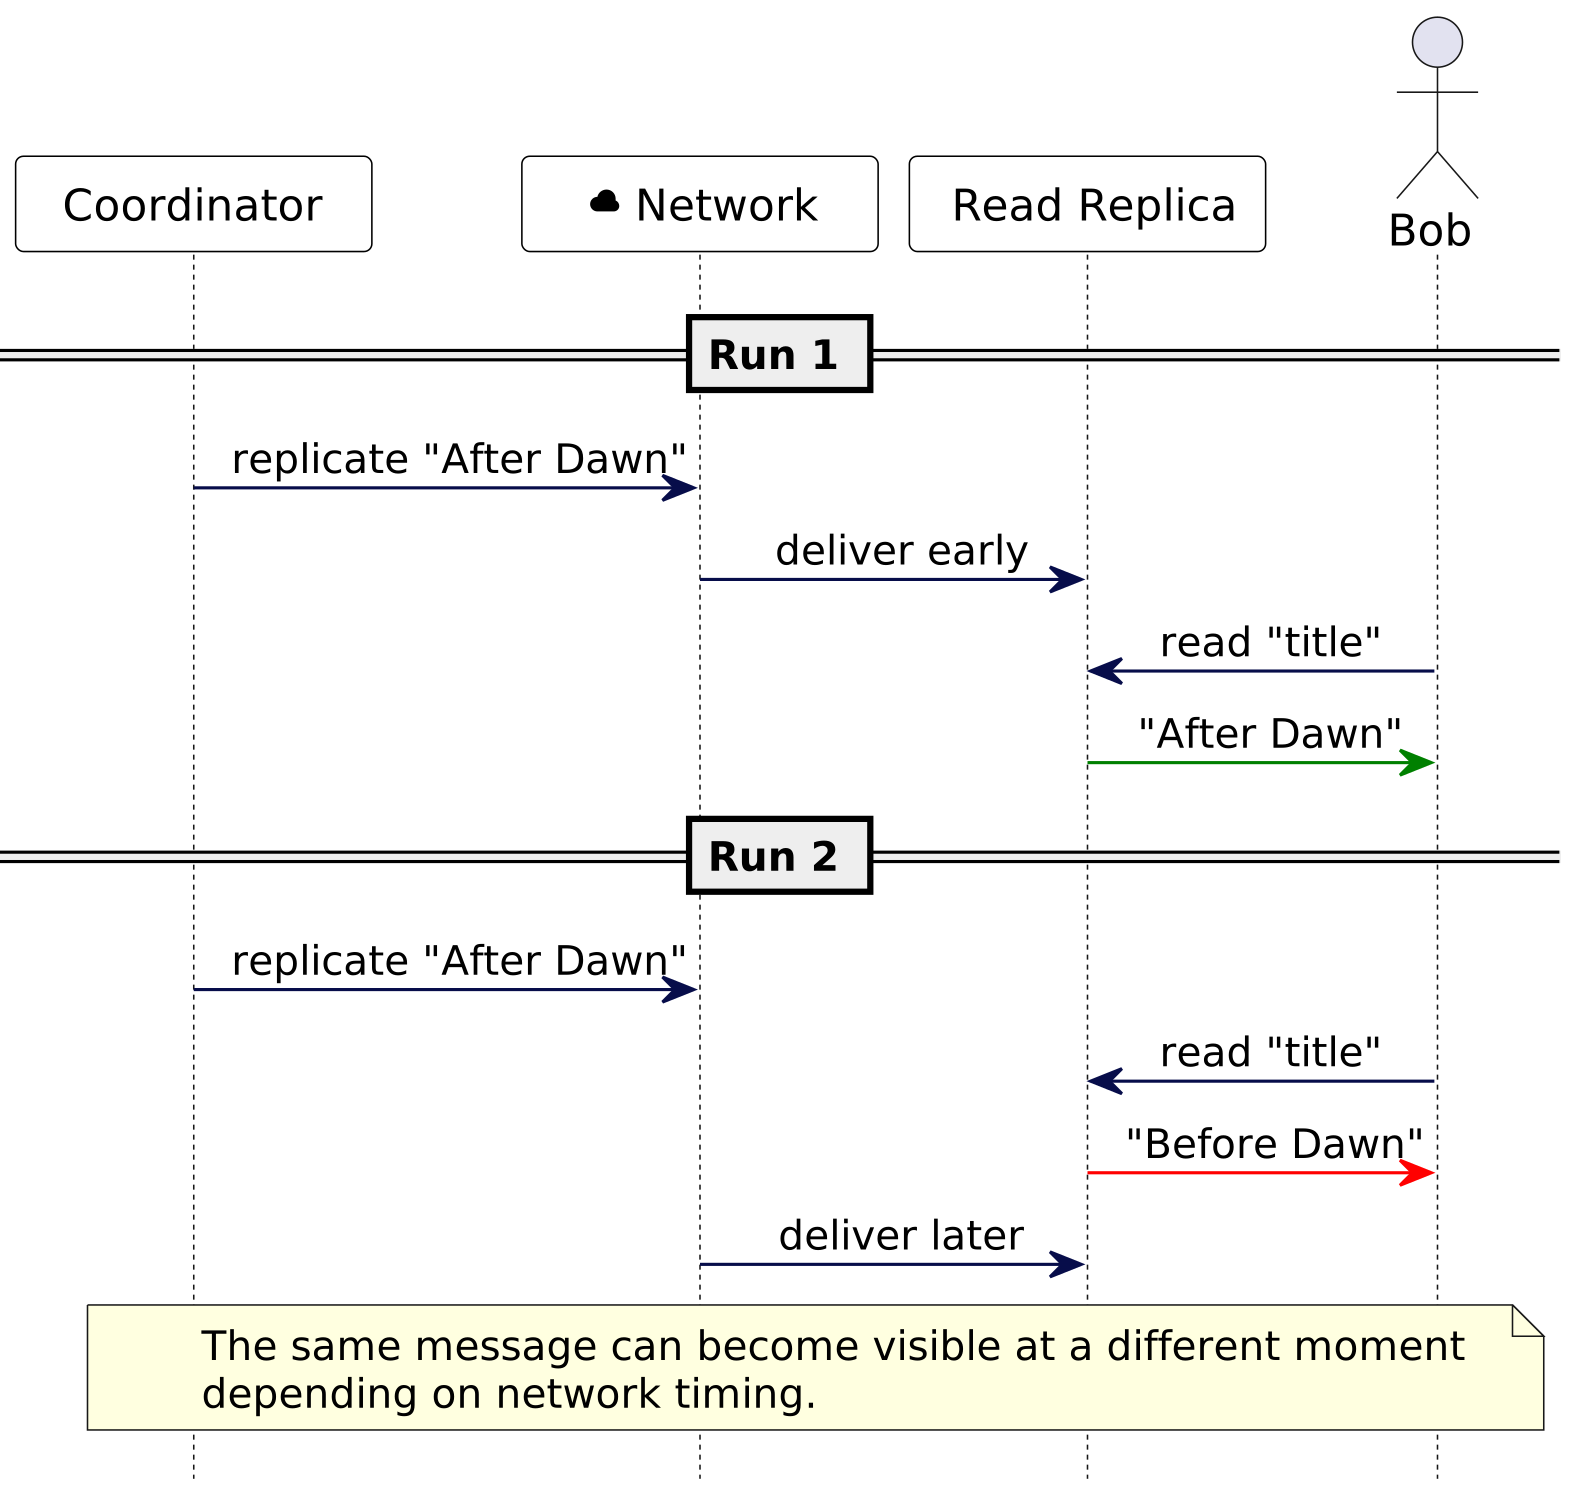
Figure 7: The same replicated message becomes visible at different times to a reader depending on network delivery timing.
Disk Timing
A write returns once the bytes are in the OS page cache, not on disk. They become durable when an fsync completes, or whenever the kernel decides to flush them. How long that takes depends on the device, its queue, and other I/O. In the figure, the coordinator crashes at the same point in both runs. In Run 1 the flush had finished and recovery finds “After Dawn”; in Run 2 it hadn't and the value is gone. To repeat a run, the test has to decide when a write becomes durable.
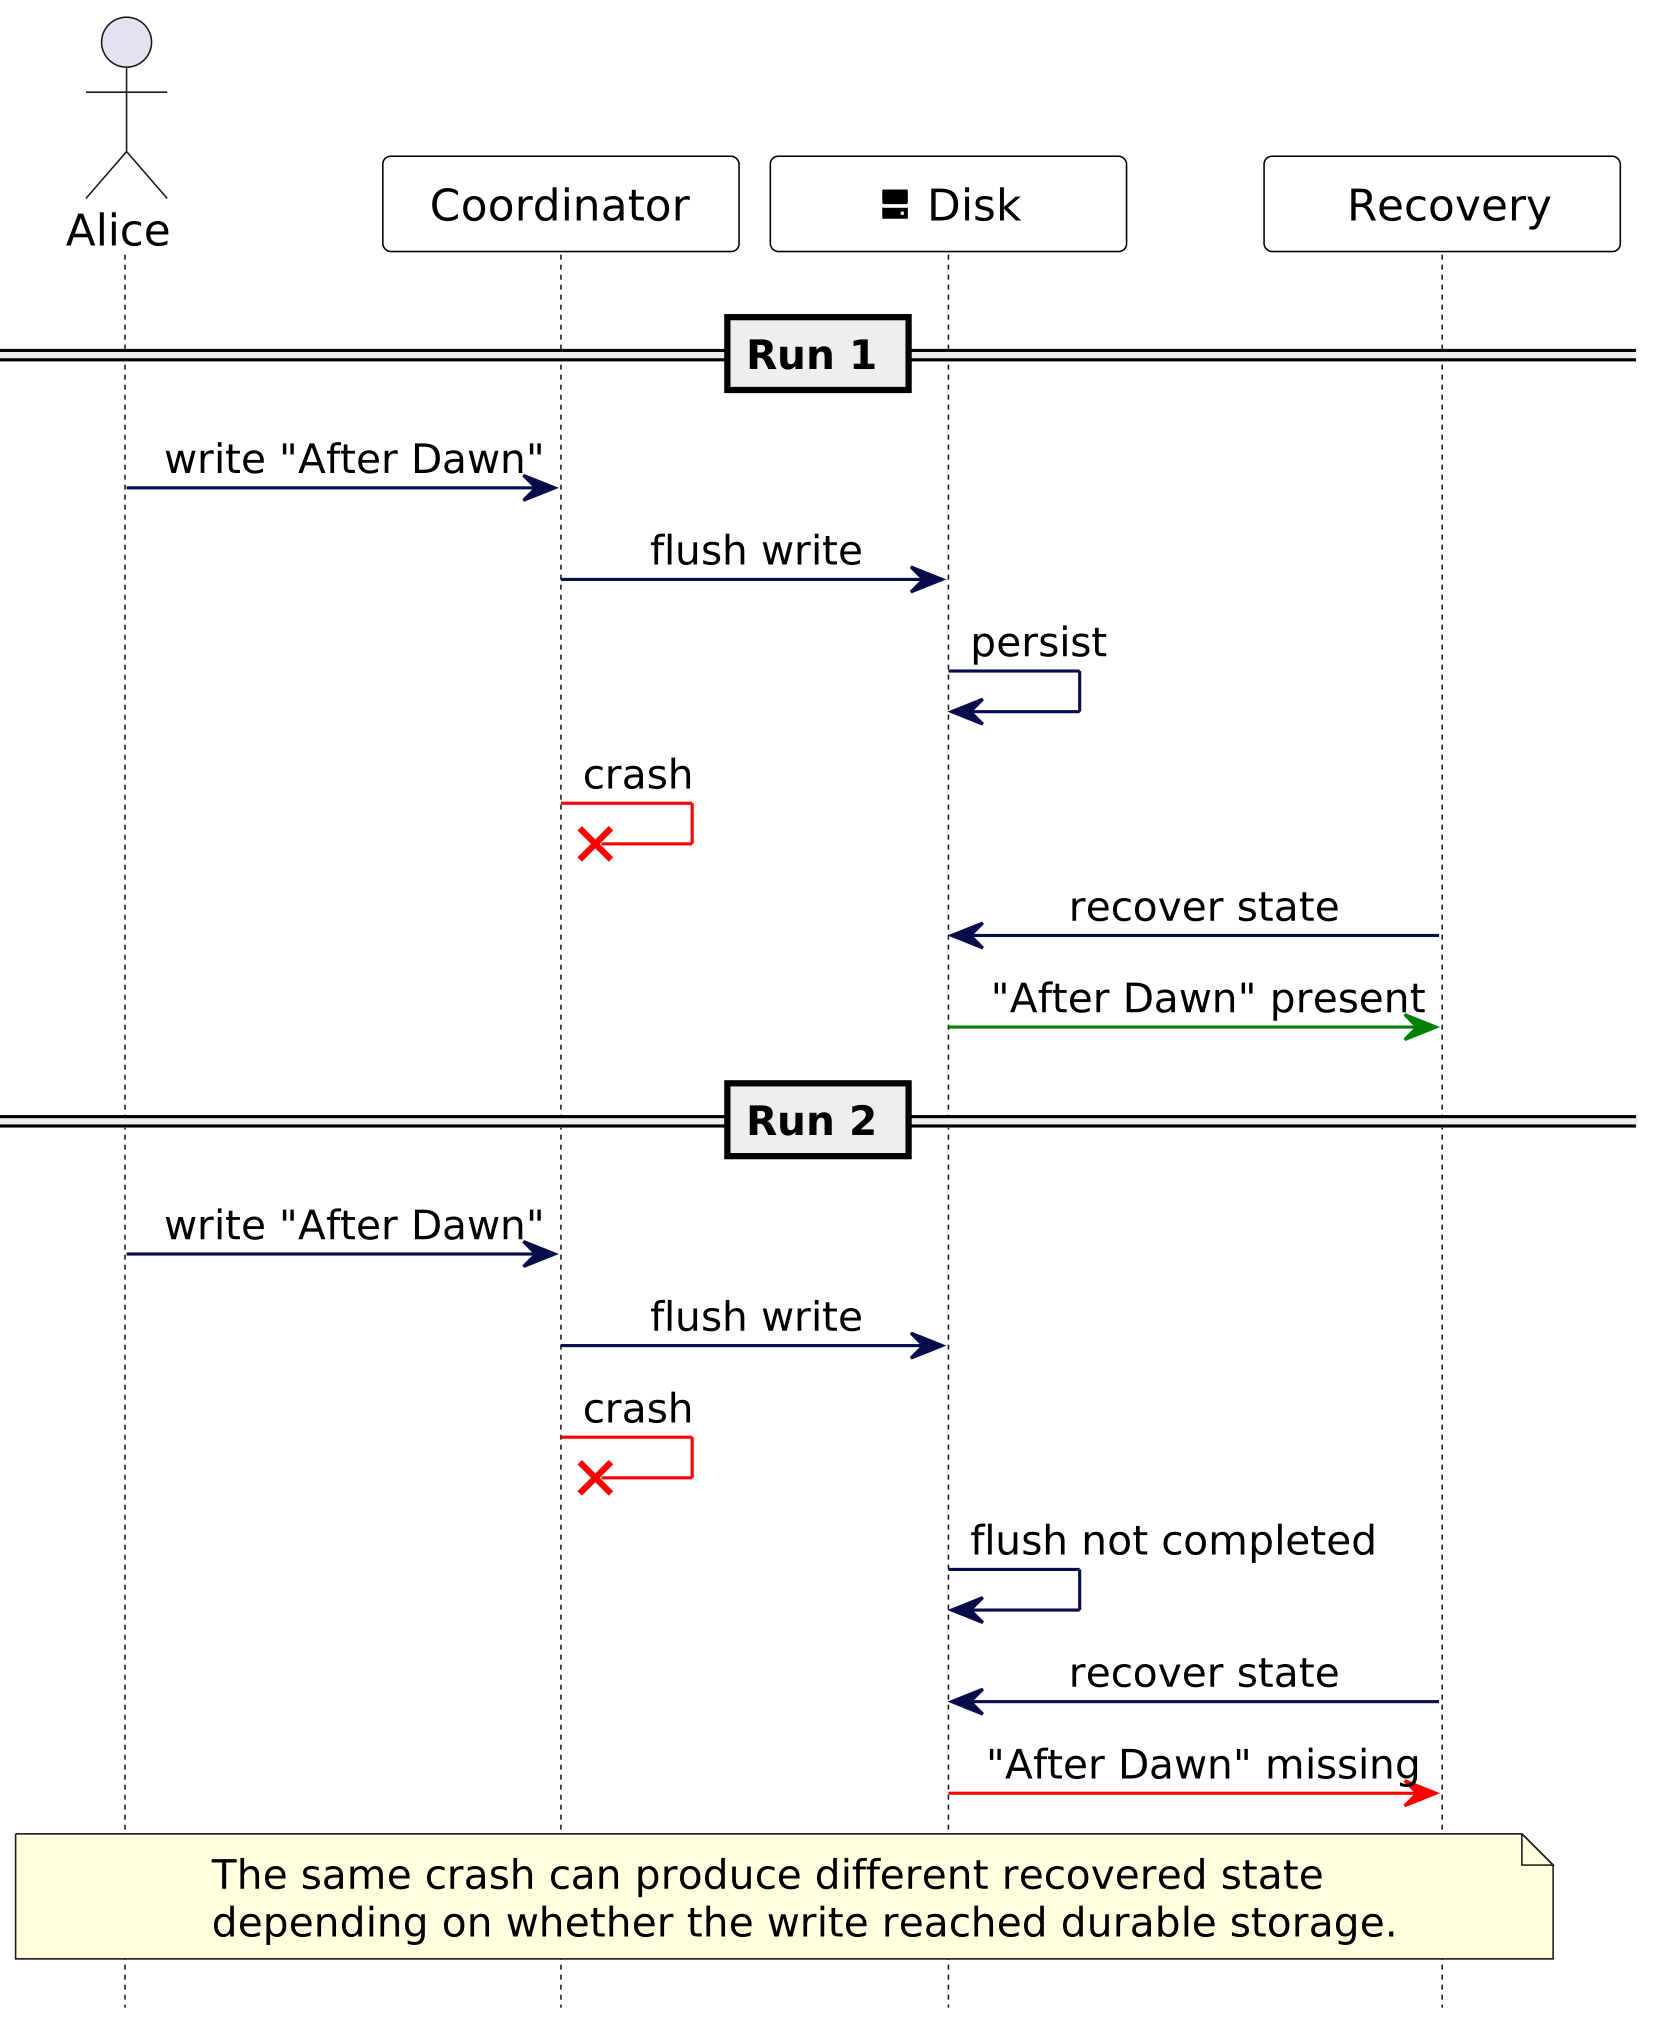
Figure 8: The same coordinator crash leads to different recovery outcomes depending on whether a write flush completed before the crash.
There are also sources inside the program itself, such as random choices and the iteration order of its data structures. These are handled by coding rules rather than by simulation, and we return to them later.
Making Progress Explicit
Real systems advance because multiple subsystems keep progressing through their own internal steps. The CPU executes instructions, the NIC delivers packets, the disk completes flushes. These progress mechanisms are hidden and not directly controlled by any test.
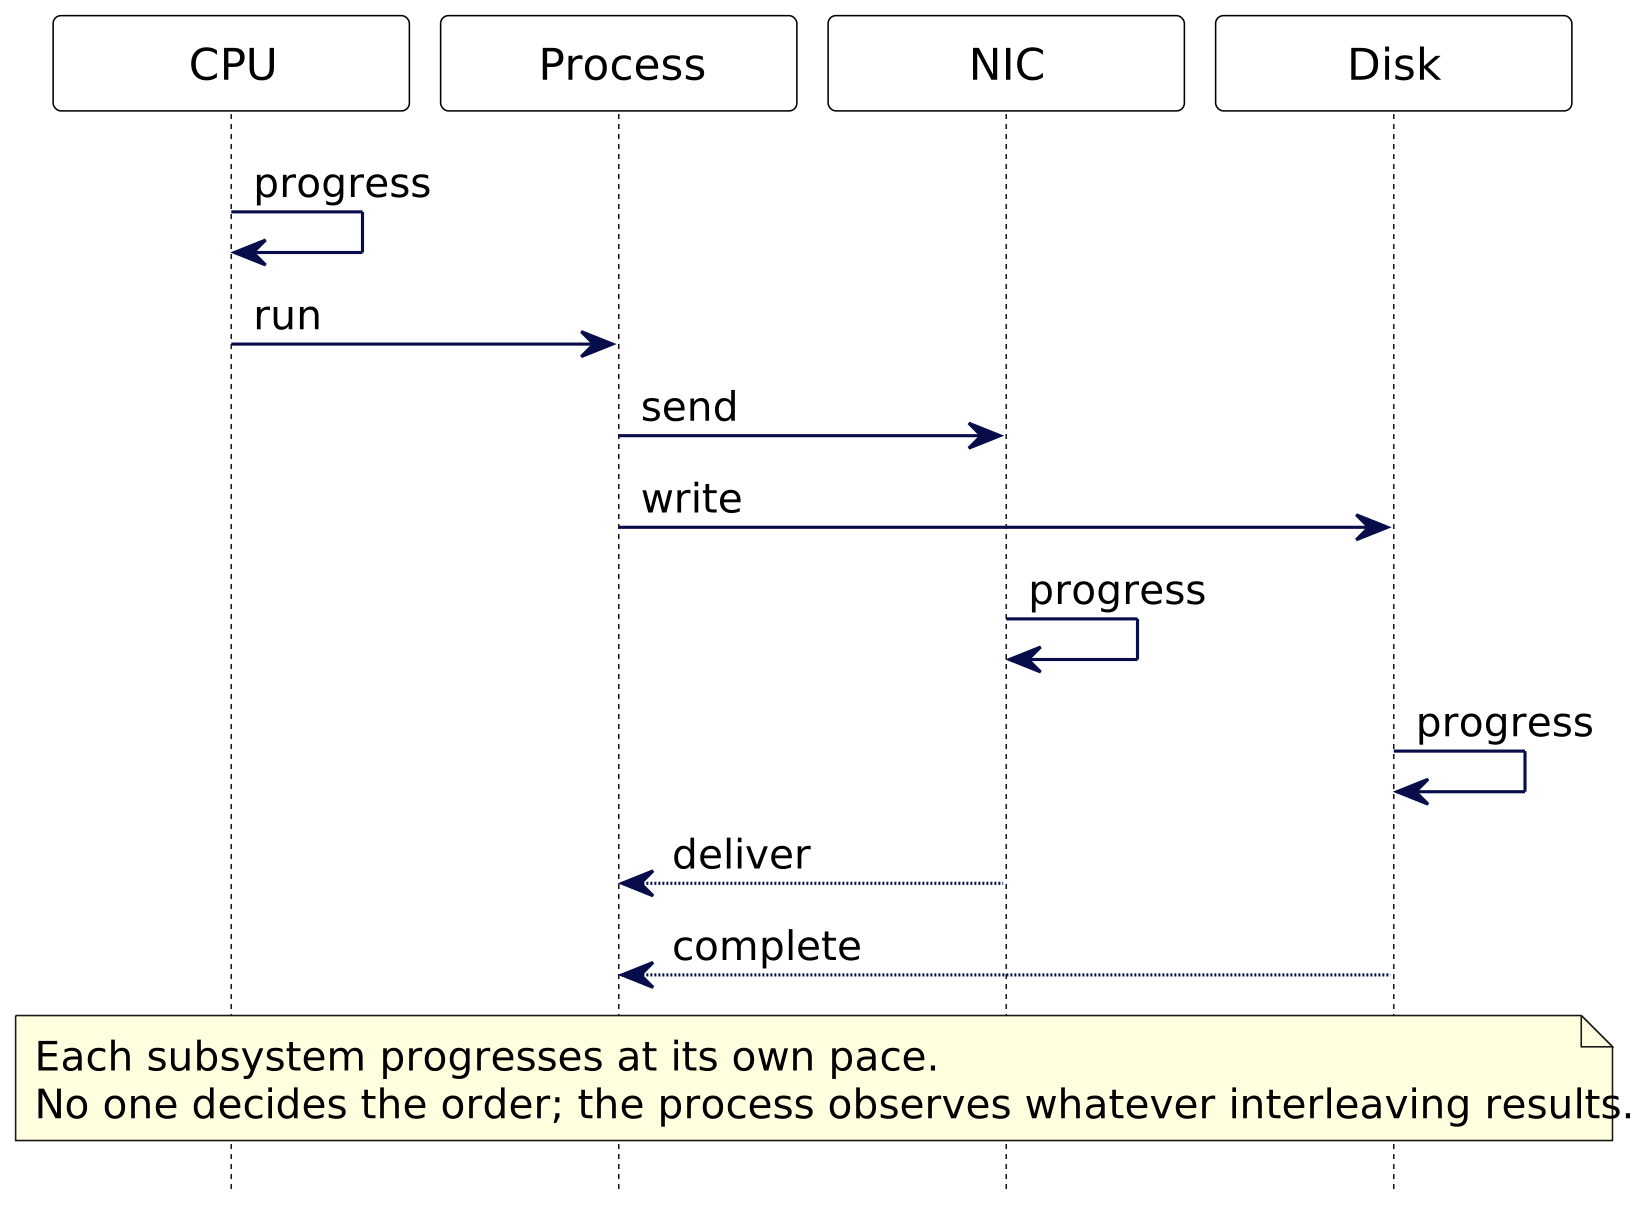
Figure 9: In a real system, CPU, NIC, and disk each progress at their own pace. Software observes the resulting interleaving of events.
To repeat a run, the test must decide when the clock, the processes, the network, and the disk make progress. This is the core idea behind deterministic simulation testing. Instead of running against real infrastructure, we run the entire cluster on a single thread against a simulated clock, a simulated network, and a simulated disk. Nothing progresses on its own. The test controls when each component executes and delivers its work.
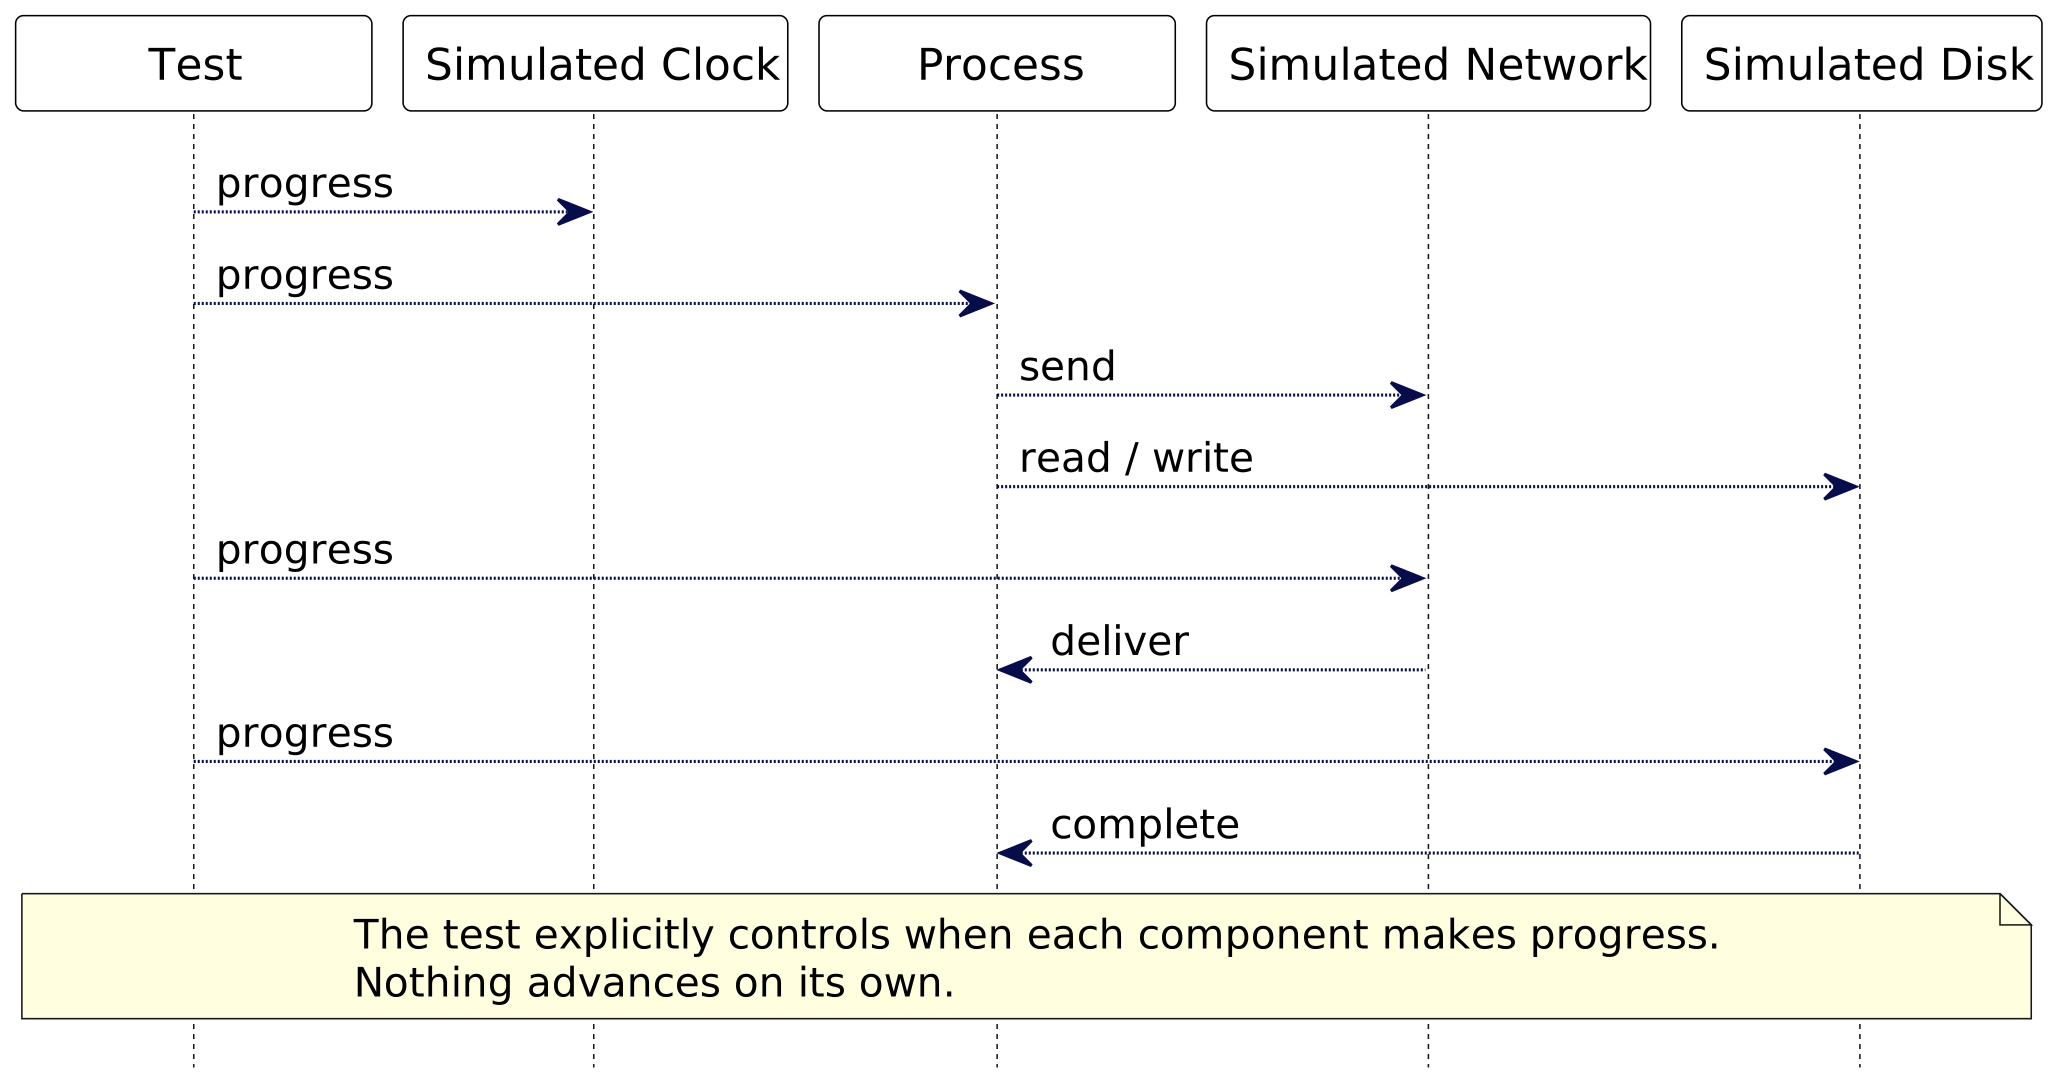
Figure 10: In simulation, the test explicitly drives progress across the clock, process, network, and disk (modeled in code as tick() calls).
Each source of nondeterminism from the previous section becomes something the test controls:
- Clock: it reads whatever the test has advanced it to.
- Thread scheduling: the whole cluster runs on one thread, and the test runs each process in a fixed order.
- Network: a message is delivered only when the test ticks the network.
- Disk: a write becomes durable only when the test ticks the disk.
Controlling progress this way makes it easy to simulate hard failures like node crashes and network partitions. More importantly, it can model routine slowdowns—a disk or network latency spike simply delays completion by a few ticks. This makes gray failures, which are otherwise extremely difficult to reproduce, straightforward to test.
Example Implementation
Let's explore an example to see how this works in code. Using Tickloom, a Java library for deterministic simulation which I built for teaching distributed systems, we will see how distributed systems can be tested by simulating network and storage.
The design of Tickloom draws heavily on FoundationDB and TigerBeetle. FoundationDB, an open-source distributed transactional key-value store, pioneered deterministic simulation testing for distributed databases using a custom C++ coroutine language and deterministic scheduler. TigerBeetle, a distributed financial transactions database, uses a clean, single-threaded, tick-driven architecture and simulator that I found easier to implement in Java. While the current Tickloom implementation is based on callbacks and a custom future, it is also possible to implement a custom deterministic scheduler using Java continuations, which is planned for future work on Tickloom.
Single-Threaded Execution
A distributed protocol implementation executes as a logical process. A cluster is a set of these processes executing across one or more physical nodes. Every process, in both testing and production, runs on a single thread. This design choice is the key, and the rest of the design, including the network and file system interfaces, follows from it.
As we saw earlier, the operating system's thread scheduler is a source
of nondeterminism. To eliminate it, we explicitly drive execution
through a single-threaded main loop.
In production, this loop runs continuously in the main method.
In testing, it runs only until a specific condition is met or
a set duration is reached. The Process abstraction maintains its own internal task queue.
The main loop controls the execution by calling an explicit tick()
API on the process, controlling exactly when it is allowed to execute
its pending tasks, handle events, and make progress.
Every component whose progress needs to be controlled—whether a process, a network, or
a file system—implements one small interface:
Tickable. Calling tick() is how a component
makes progress: delivering messages, completing I/O, or running
pending tasks. The loop needs to know nothing about component
internals; it simply calls tick() on each in a fixed
order. Because components only advance when ticked, their state
never changes between ticks.
public interface Tickable {
    void tick();
}
The main thread executing the tick calls must never block. In production, a node blocked waiting for a reply would stop serving every other request. To make sure single-threaded execution happens without blocking, we do the following:
- Network and storage calls are asynchronous.
- Asynchronous APIs are modeled using a custom future that allows standard composition but has no blocking get method and strictly prevents the use of background threads.
- No
Thread.sleep()and no blocking calls. - Production network tasks use non-blocking Java NIO. Blocking filesystem work that must run on a background thread hands its results back to the node's main thread as events, which are only processed during a tick.
Simulating the Network
To control when messages arrive, we should be able to swap the network implementation with a simulated one.
The protocol code must not notice the difference: the
same code has to run against the simulated network in a test
and against real sockets in production. So the core protocol logic never touches
sockets directly. It talks to the network only through an
interface, Network.
What travels over the network is a Message.
public record Message(
        ProcessId source,
        ProcessId destination,
        PeerType peerType,
        MessageType messageType,
        byte[] payload,
        String correlationId
)
It names its source and destination processes, its type, and carries an encoded payload. The correlation ID maps a response to the request.
The interface is asynchronous, because the process runs on a single
thread that must never block. send() hands a message
to the network and returns at once. It does not wait for the
message to be delivered, or for a reply. Messages arriving for
a particular process are delivered to the registered Process by calling
its onMessage() method. A reply is just another
message that arrives some ticks later. The network also has a
tick(), which drives its work.
public abstract class Network implements Tickable, AutoCloseable {
    private final ProcessRegistry registry = new ProcessRegistry();

    public void register(Process process) {
        registry.register(process);
    }

    public Set<ProcessId> registeredProcessIds() {
        return registry.processIds();
    }

    protected void deliver(Message message) {
        Optional<Process> process = registry.get(message.destination());
        if (process.isEmpty()) {
            logDropped(message);
            return;
        }
        process.get().onMessage(message);
    }

    @Override
    public abstract void tick();

    public abstract void send(Message message) throws IOException;

    public void bind(ProcessId processId) throws IOException {
        //no-op.. only used by NioNetwork
    }

    @Override
    public void close() throws Exception {

    }
There are two implementations of the Network interface:
- In tests:
SimulatedNetworkpasses messages directly between processes in memory. This is the implementation that supports injecting faults like network partitions, message loss and message delays. - In production:
NioNetworkimplements the same non-blocking contract over real TCP sockets using Java NIO and a singleSelector.send()non-blockingly enqueues encoded messages on aNioConnection, and the event loop flushes writes and dispatches incoming messages.
The simulated network has no sockets. It routes messages directly to processes in memory, implementing the two contract methods.
It keeps track of NetworkLinks between pairs of processes and applies
configuration to these links in terms of delays, drop rates, and congestion:
class SimulatedNetwork
  private record NetworkLink(ProcessId source, ProcessId destination) {
      boolean isPartitioned(Set<NetworkLink> partitionedLinks) {
          return partitionedLinks.contains(this);
      }
  }
The simulated network tracks partitions, packet drop rates, and delays across these links:
class SimulatedNetwork
  private final Set<NetworkLink> partitionedLinks = new HashSet<>();
  private final Map<NetworkLink, Double> linkPacketLoss = new HashMap<>();
  private final Map<NetworkLink, DelayConfig> cloggedUntilTick = new HashMap<>();
  private final Map<NetworkLink, FaultRule> linkFaultRules = new HashMap<>();
How send() Works
When a message is sent, the network checks the simulated link between the sender and receiver. If the link is partitioned, or matches a drop rule, the message is discarded.
class SimulatedNetwork
  @Override
  public void send(Message message) {
      validateMessage(message);

      NetworkLink link = linkFrom(message);

      if (link.isPartitioned(partitionedLinks)) {
          return; // Message dropped due to partition
      }

      if (matchesFaultRule(link, message)) {
          return; // Message dropped due to fault rule
      }

      if (shouldDropPacket(link)) {
          return; // Message lost due to packet loss
      }

      // Use internal counter to calculate delivery tick (TigerBeetle pattern)
      long deliveryTick = calculateDeliveryTick(link, message, currentTick);
      queueForDelivery(message, deliveryTick);
  }
A message that survives is not delivered immediately; it is placed in a priority queue stamped with its delivery tick (the next tick, or later if delayed or clogged) and an incrementing sequence number to guarantee deterministic FIFO ordering.
private void queueForDelivery(Message message, long deliveryTick) {
    pendingMessages.offer(new QueuedMessage(message, deliveryTick, nextSequenceNumber++));
}
How tick() Works
Nothing in the queue moves until the network is ticked. On each
tick(), the network advances its virtual tick counter,
applies any dynamic fault changes, and delivers every message due for
the current tick.
class SimulatedNetwork
  @Override
  public void tick() {
      currentTick++; // Increment internal counter (TigerBeetle pattern)
      maybeFlipPartitions();
      maybeClogPaths();
      deliverPendingMessagesFor(currentTick);
  }
Messages due at the same tick are delivered in the order they were sent.
Delivering a message simply calls deliver(message), which routes it to the
destination process's onMessage() method.
class SimulatedNetwork
  private void deliverPendingMessagesFor(long tickTime) {
      // Process messages whose delivery time has now arrived
      // PriorityQueue ensures we process in delivery time order
      while (!pendingMessages.isEmpty() &&
              pendingMessages.peek().deliveryTick <= tickTime) {

          QueuedMessage queuedMessage = pendingMessages.poll();
          Message message = queuedMessage.message;
          deliver(message);

          System.out.println("SimNet: delivered " + message + " for tick " + tickTime);
      }
  }
Routing Messages to Processes
All communication in the cluster happens between processes, identified by
a ProcessId. In production, a process opens TCP sockets to
peers across the physical network. In simulation, however, every process
in the cluster—servers and clients alike—shares a single
SimulatedNetwork instance in memory. The network routes
messages by maintaining an internal registry of active processes: when a
process initializes, it registers its ProcessId, allowing the
network to dispatch incoming messages directly to that process's
onMessage() method. A message for an ID nobody registered is
logged and dropped.
A process is given its network when it is created. It never creates the network itself, which is what lets a test hand it the simulated one.
public abstract class Process implements Tickable, AutoCloseable {
    public final ProcessId id;
    public final Network network;
In its constructor, the process registers with the network, so that messages addressed to its ID reach it, and then sets up its message handlers.
network.register(this);
initialiseMessageHandlers();
Each implementation needs to handle different kinds of messages. A handler is an interface that allows providing a protocol specific implementation.
class Process
  protected interface Handler {
      void handle(Message message);
  }

  protected Map<MessageType, Handler> handlers = new HashMap<>();

  private void initialiseMessageHandlers() {
      this.handlers.putAll(initialiseHandlers());
  }

  protected abstract Map<MessageType, Handler> initialiseHandlers();

  protected Handler getHandler(MessageType messageType) {
      return handlers.get(messageType);
  }
The QuorumReplica, for example, handles client requests and the
internal requests and responses between replicas:
class QuorumReplica
  @Override
  protected Map<MessageType, Handler> initialiseHandlers() {
      return Map.of(
              QuorumMessageTypes.CLIENT_GET_REQUEST, this::handleClientGetRequest,
              QuorumMessageTypes.CLIENT_SET_REQUEST, this::handleClientSetRequest,
              QuorumMessageTypes.INTERNAL_GET_RESPONSE, this::handleInternalGetResponse,
              QuorumMessageTypes.INTERNAL_SET_RESPONSE, this::handleInternalSetResponse,
              QuorumMessageTypes.INTERNAL_GET_REQUEST, this::handleInternalGetRequest,
              QuorumMessageTypes.INTERNAL_SET_REQUEST, this::handleInternalSetRequest);
  }
The network calls onMessage, which runs the
handler for the message's type.
class Process
  public final void onMessage(Message message) {
      if (state == ProcessState.STOPPED) {
          return;
      }
      onMessageReceived(message);
      MessageType messageType = message.messageType();
      Handler handler = getHandler(messageType);
      if (handler == null) {
          System.err.println("No handler found for message " + messageType);
          return;
      }

      // Check if process is running before handling message
      if (state != ProcessState.RUNNING) {
          System.err.println(id + ": Received message " + messageType + " but process not initialized yet");
          handleUninitializedMessage(message);
          return;
      }

      handler.handle(message);
  }
The handler runs to completion on the main thread. If it needs to communicate with another process, it creates a message and sends it through the network; the response arrives later as another message.
Timeouts in Ticks
A timeout cannot be measured with a
time-of-day clock, because it is not guaranteed to be monotonic.
A common workaround is to
use monotonic clocks to measure elapsed time, but a process pause can
cause issues with this measurement. To make timeouts deterministic,
they are decoupled from any clock, and are based on a logical counter
representing elapsed time. A Timeout counts
ticks. A timeout of 10 expires after exactly
10 calls to tick().
public final class Timeout {

    private final String name;
    private final long durationTicks;
    private long ticks = 0;
    private boolean ticking = false;
    private long startTick = 0;

    /**
     * Creates a new timeout with the specified duration.
     *
     * @param name human-readable name for debugging
     * @param durationTicks number of ticks before timeout fires
     */
    public Timeout(String name, long durationTicks) {
        this.name = name;
        this.durationTicks = durationTicks;
    }

    public void start() {
        ticking = true;
        startTick = ticks;
    }

    public void tick() {
        ticks++;
    }

    public boolean isExpired() {
        if (!ticking) {
            return false;
        }
        return (ticks - startTick) >= durationTicks;
    }
To track in-flight requests and their timeouts without blocking,
processes use a
Request Waiting List.
The coordinator and the client register each request with its own
Timeout when it is added:
class RequestWaitingList
  public void add(Key key, RequestCallback<Response> callback) {
      //create Timeout with configured timeoutTicks.
      Timeout timeout = new Timeout("request-" + key, timeoutTicks);
      timeout.start();
      pendingRequests.put(key, new CallbackDetails(callback, timeout));
  }
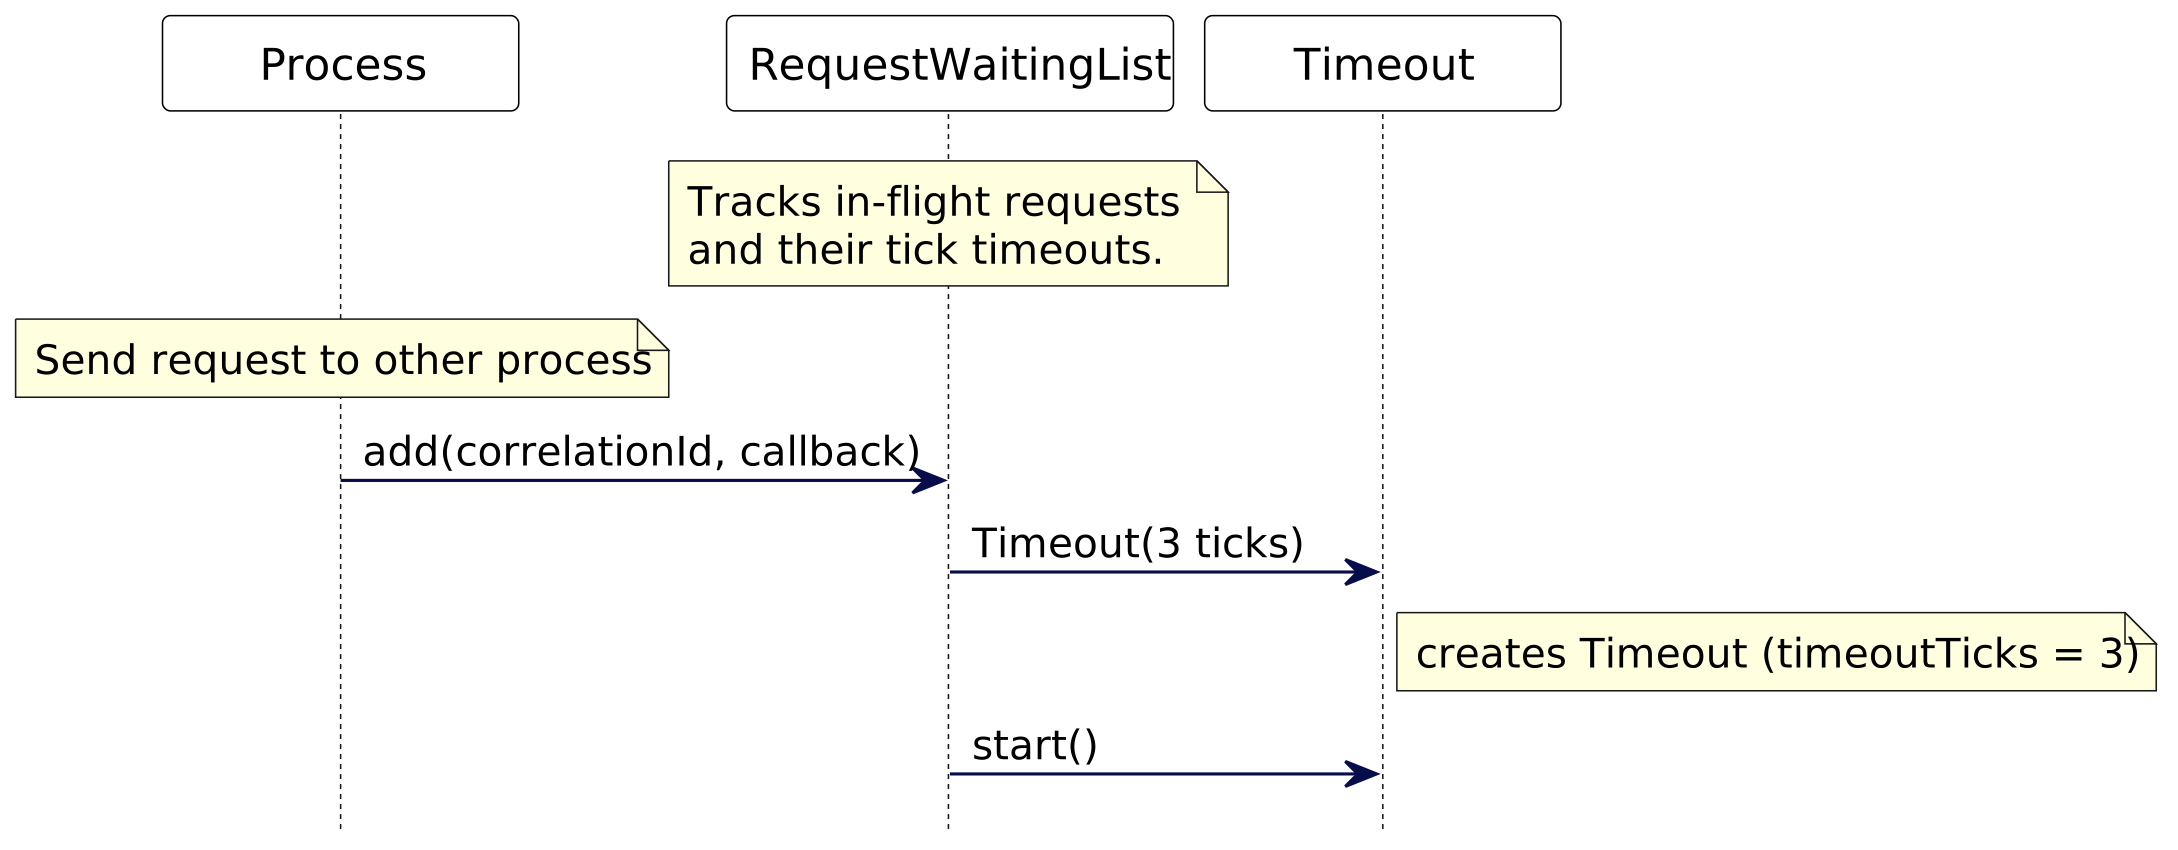
Figure 11:
When a request is added, the waiting list creates and starts a
tick-based Timeout.
On each tick, the waiting list advances the timeout counter and checks whether it has expired.
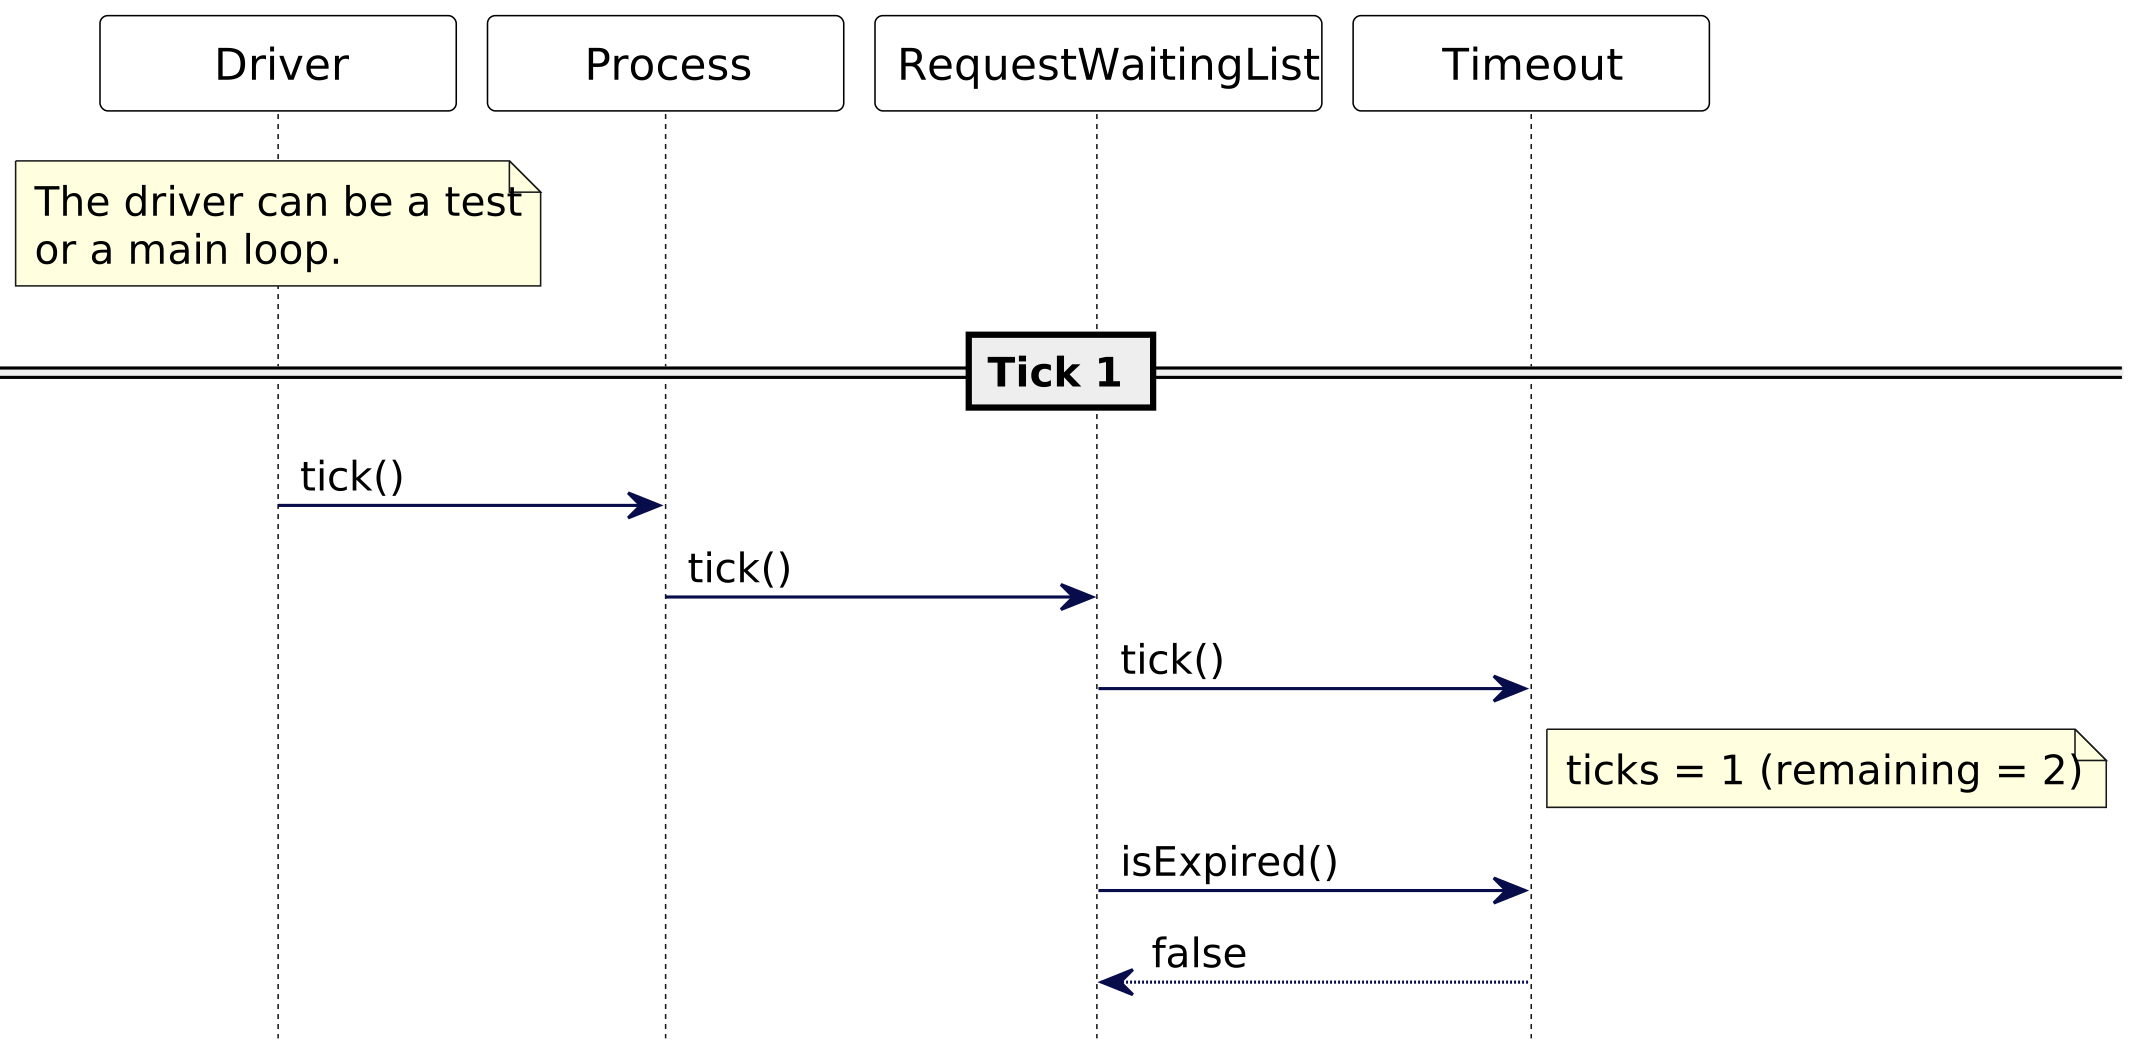
Figure 12: On each tick, the waiting list advances the timeout counter and checks whether it has expired.
On the third tick the timeout has expired. So the associated request is expired with a TimeoutException:
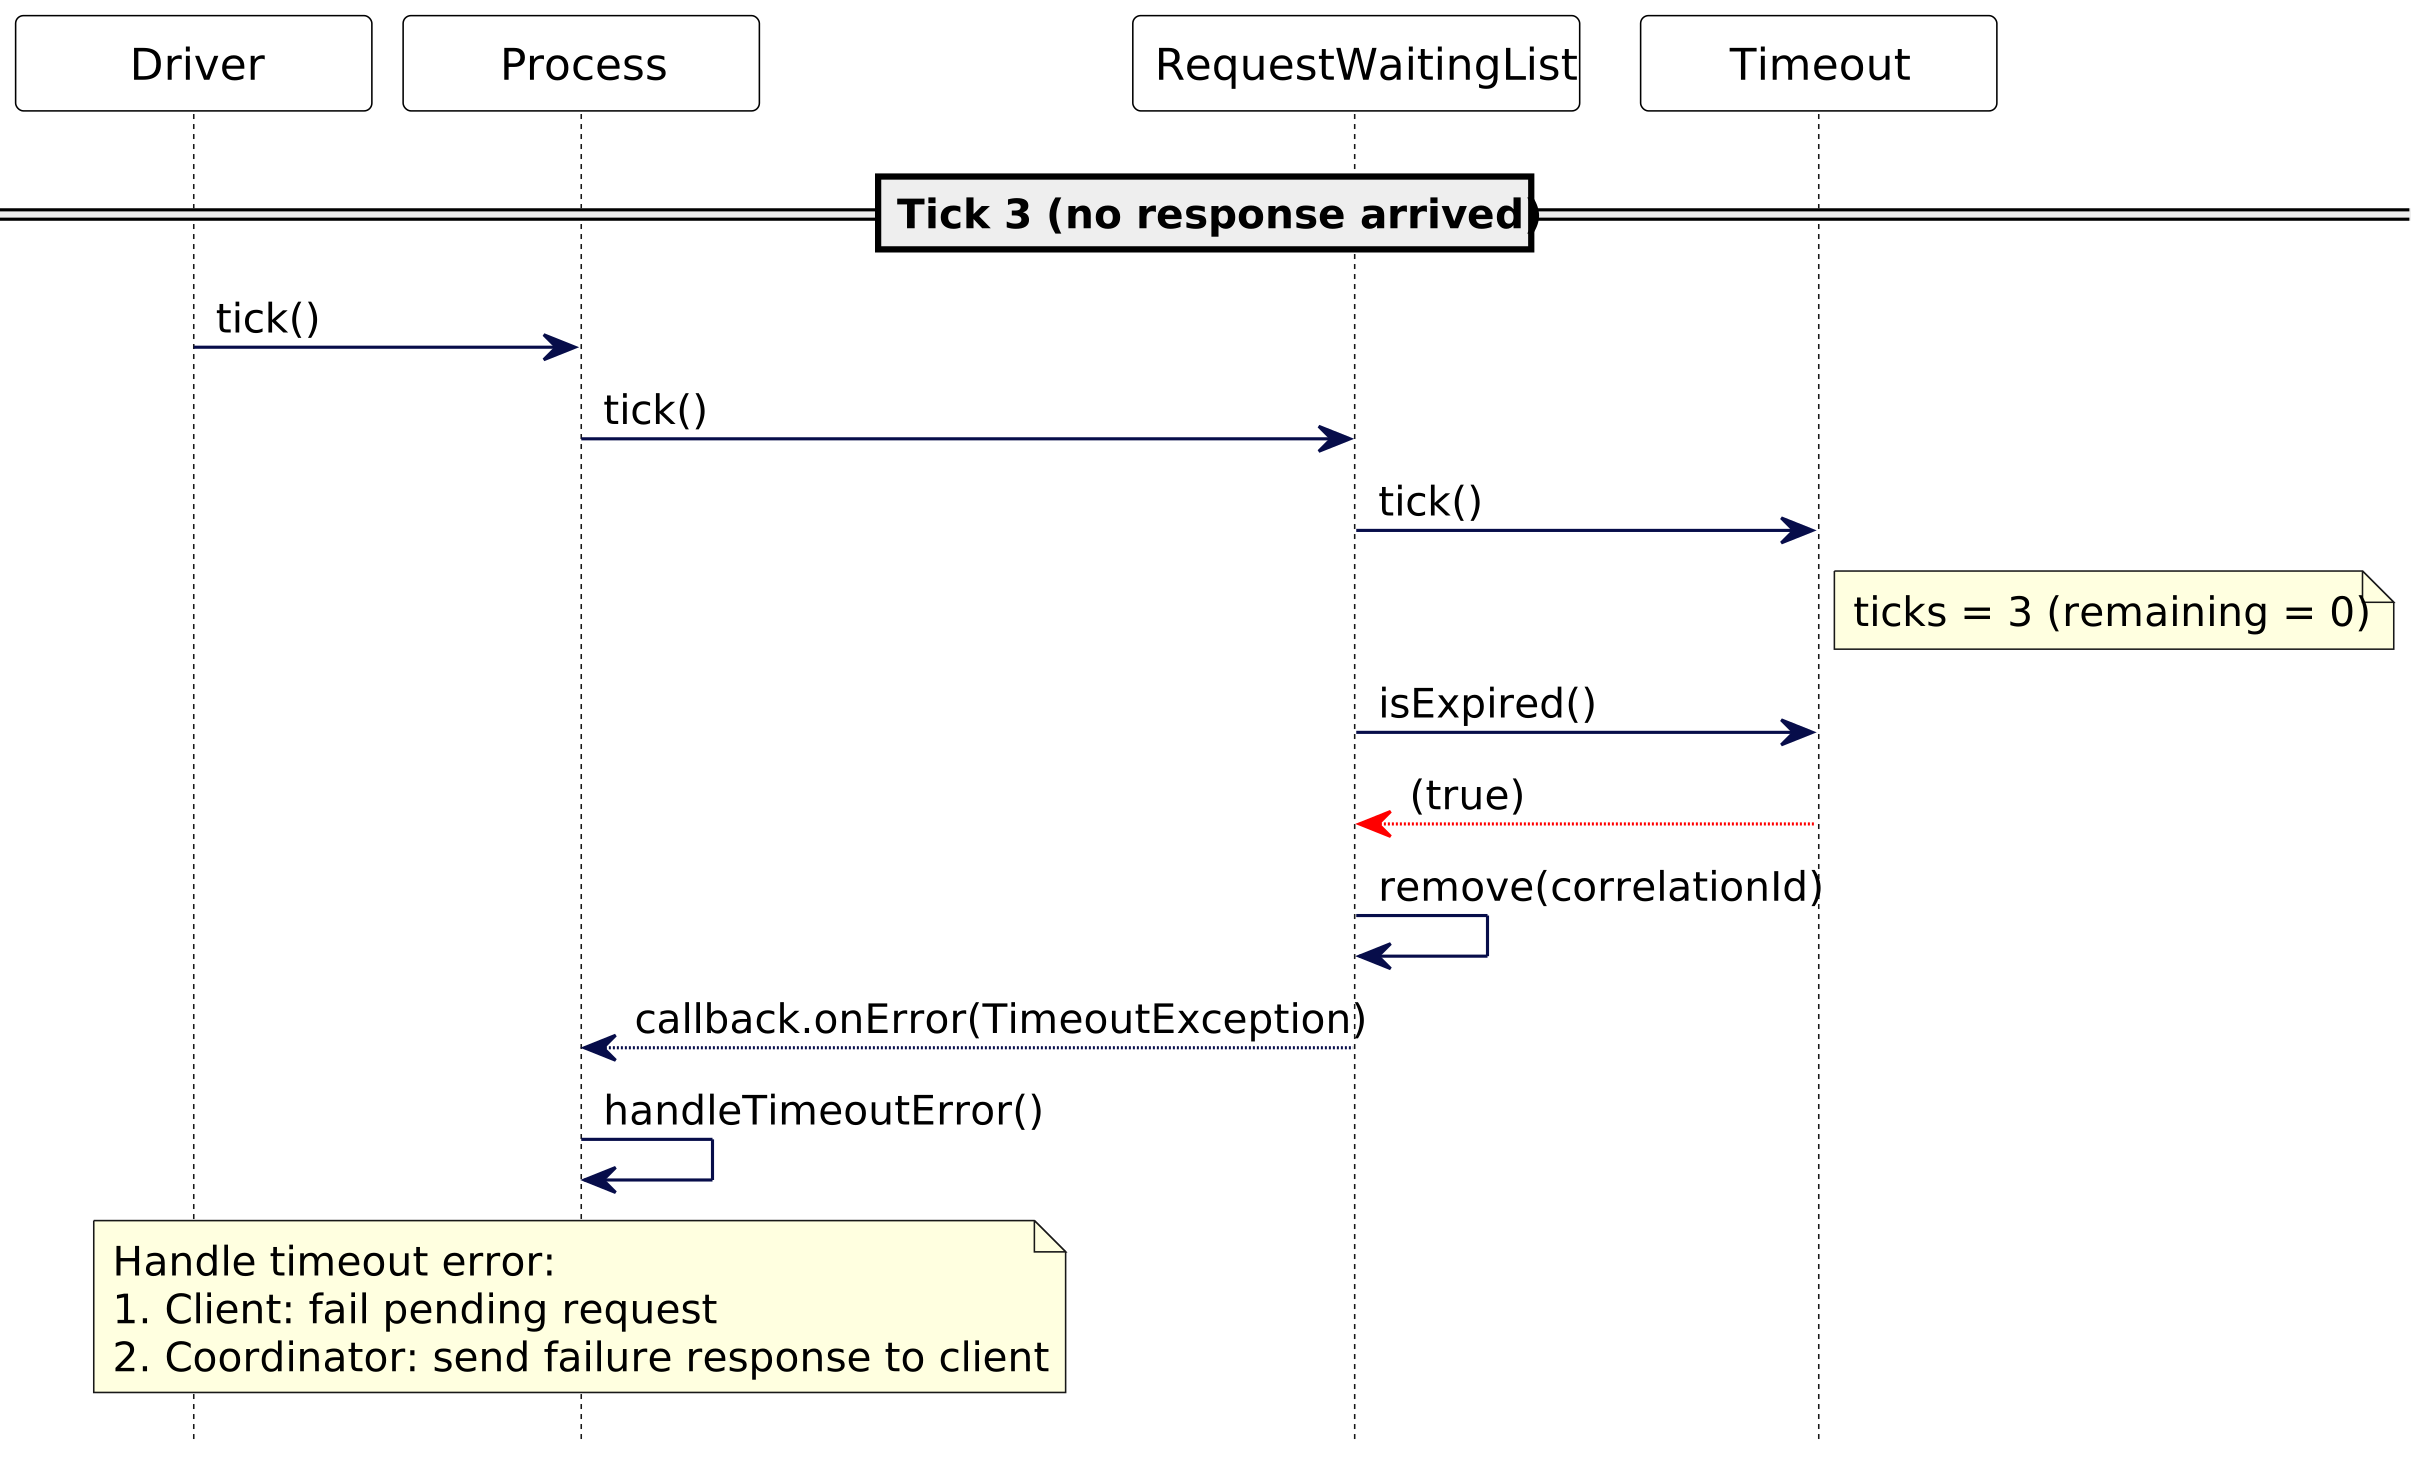
Figure 13:
When a timeout expires, the waiting list removes the request
and throws a TimeoutException.
class RequestWaitingList
  public void tick() {
      // First, tick all timeouts
      pendingRequests.values().forEach(callbackDetails ->
          callbackDetails.getTimeout().tick());

      List<Key> expiredRequestKeys = getExpiredRequestKeys();
      if (expiredRequestKeys.isEmpty()) {
          return;
      }

      timeoutExpiredRequests(expiredRequestKeys);
  }

  private void timeoutExpiredRequests(List<Key> expiredRequestKeys) {
       expiredRequestKeys.forEach(expiredRequestKey -> {
          CallbackDetails callbackDetails = pendingRequests.remove(expiredRequestKey);
          if (callbackDetails != null) {
              callbackDetails.getRequestCallback().onError(
                  new TimeoutException("Request expired after " + timeoutTicks + " ticks")
              );
          }
      });
  }

  private List<Key> getExpiredRequestKeys() {
      return pendingRequests.entrySet().stream()
              .filter(entry -> entry.getValue().isExpired())
              .map(Map.Entry::getKey)
              .collect(Collectors.toList());
  }
Testing with a Simulated Cluster
The QuorumReplica is the store from the earlier example. When a client sends a set
request, the replica that receives it acts as the coordinator. It
stamps the value with its clock and sends an internal set request
to all three replicas, including itself. It replies to the client
once a majority have acknowledged, and fails the write if no
majority answers before its request times out.
The earlier example had two runs of the same write with Cyrene isolated. In Run 1 Byzantium's acknowledgment arrived in time; in Run 2 it was delayed and the write timed out. In a live cluster, nothing in the test decided which run we got. In the simulation, the test decides.
A test builds a Cluster of quorum replicas on a simulated network, with a request timeout
of 10 ticks. It isolates Cyrene, and delays the link from
Byzantium to Athens by 20 ticks. Then Alice sends the write to
Athens, and the test ticks the cluster until the write is no
longer pending.
class QuorumWriteTimeoutTest
  @Test
  void writeTimesOutWhenAcknowledgmentIsDelayed() throws IOException {
      try (Cluster cluster = new Cluster()
              .withProcessIds(List.of(ATHENS, BYZANTIUM, CYRENE))
              .withRequestTimeoutTicks(10)
              .useSimulatedNetwork()
              .build(QuorumReplica::new)) {
          cluster.start();

          cluster.isolateProcess(CYRENE);
          cluster.setNetworkDelay(BYZANTIUM, ATHENS, 20);

          QuorumReplicaClient alice =
                  cluster.newClientConnectedTo(ALICE, ATHENS, QuorumReplicaClient::new);
          TickCompletableFuture<SetResponse> write =
                  alice.set("title".getBytes(), "After Dawn".getBytes());
          cluster.tickUntil(() -> !write.isPending());

          assertTrue(write.isFailed());
      }
  }
Cluster is a test utility that builds a cluster of given
processes—in this case QuorumReplica processes—and wires
them to the shared simulated network. It provides helper methods to
introduce faults (such as isolating processes and delaying links) as
well as to drive execution and verify assertions.
class Cluster
  public void tick() {
      advanceClocks();
      tickNetworks();
      tickClients();
      tickServers();
  }

  private void advanceClocks() {
      processClocks.values().forEach(clock -> clock.advance(1));
  }

  private void tickServers() {
      serverNodes.forEach(Node::tick);
  }

  private void tickClients() {
      clientNodes.forEach(ClientNode::tick);
  }

  private void tickNetworks() {
      networks.forEach(Network::tick);
  }
Instead of sleeping, tests call tickUntil to advance the cluster
until an expected condition holds.
class Cluster
  public void tickUntil(BooleanSupplier p) {
      int tickCount = 0;
      while (!p.getAsBoolean()) {
          if (tickCount > DEFAULT_TIMEOUT_TICKS) {
              fail("Timeout waiting for condition to be met.");
          }
          tick();
          tickCount++;
      }
  }
Athens's own write is durable within a few ticks. Byzantium's acknowledgment leaves Byzantium a few ticks later, and arrives 20 ticks after that. The timeout expires first, and the write fails. It fails on every run. Set the delay to one tick and it succeeds on every run.
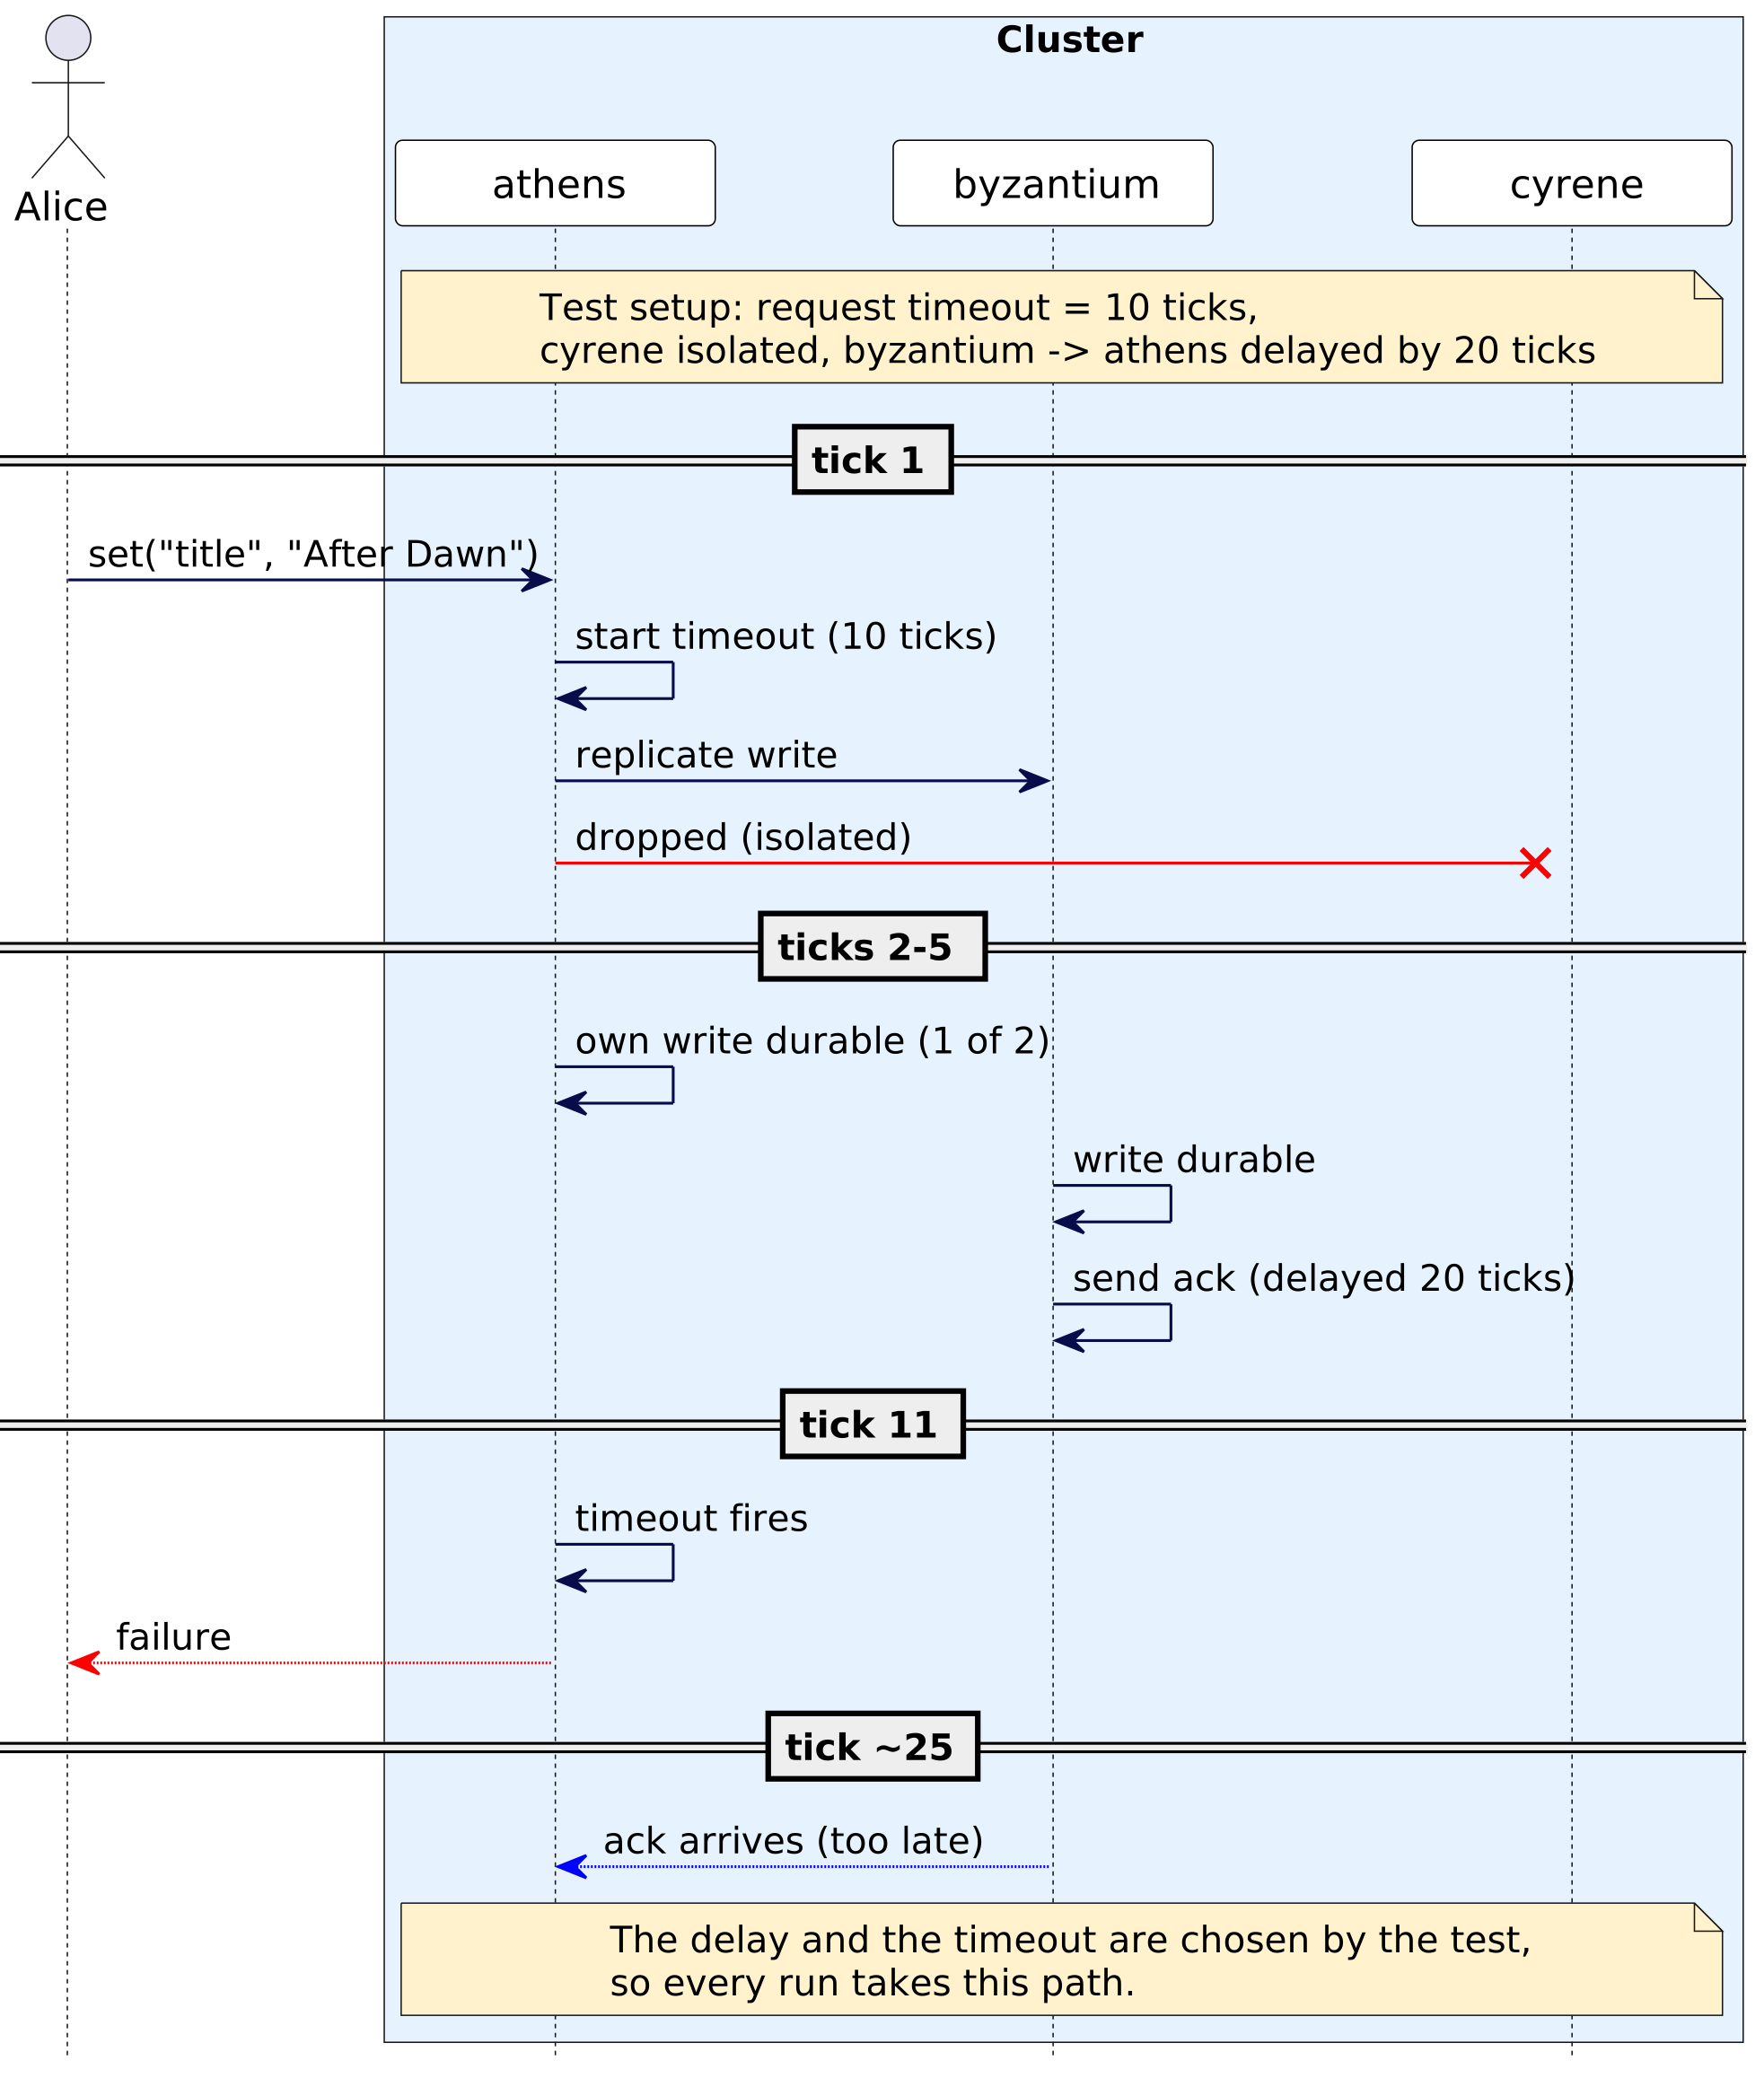
Figure 14: Run 2 in simulation: with Cyrene isolated and the link from Byzantium delayed by 20 ticks, the 10-tick timeout fires before the acknowledgment arrives, on every run.
The outcome now depends only on numbers the test chose: the delay and the timeout. If a bug lived on the Run 2 path, this test would hit it every time.
Seeded Fault Injection
So far we discussed how to write tests for known fault interaction scenarios. This is mostly useful for learning and teaching. Production systems reveal bugs caused by interesting interleavings only after they are up and running for a longer duration. A common approach is to keep a system running for hours and introduce random failures. This is a good practical way to explore the huge state space of all possible fault interactions. Typically, a pseudorandom generator is used to decide when to inject a fault. Making it seeded for every run, makes sure the run is repeatable.
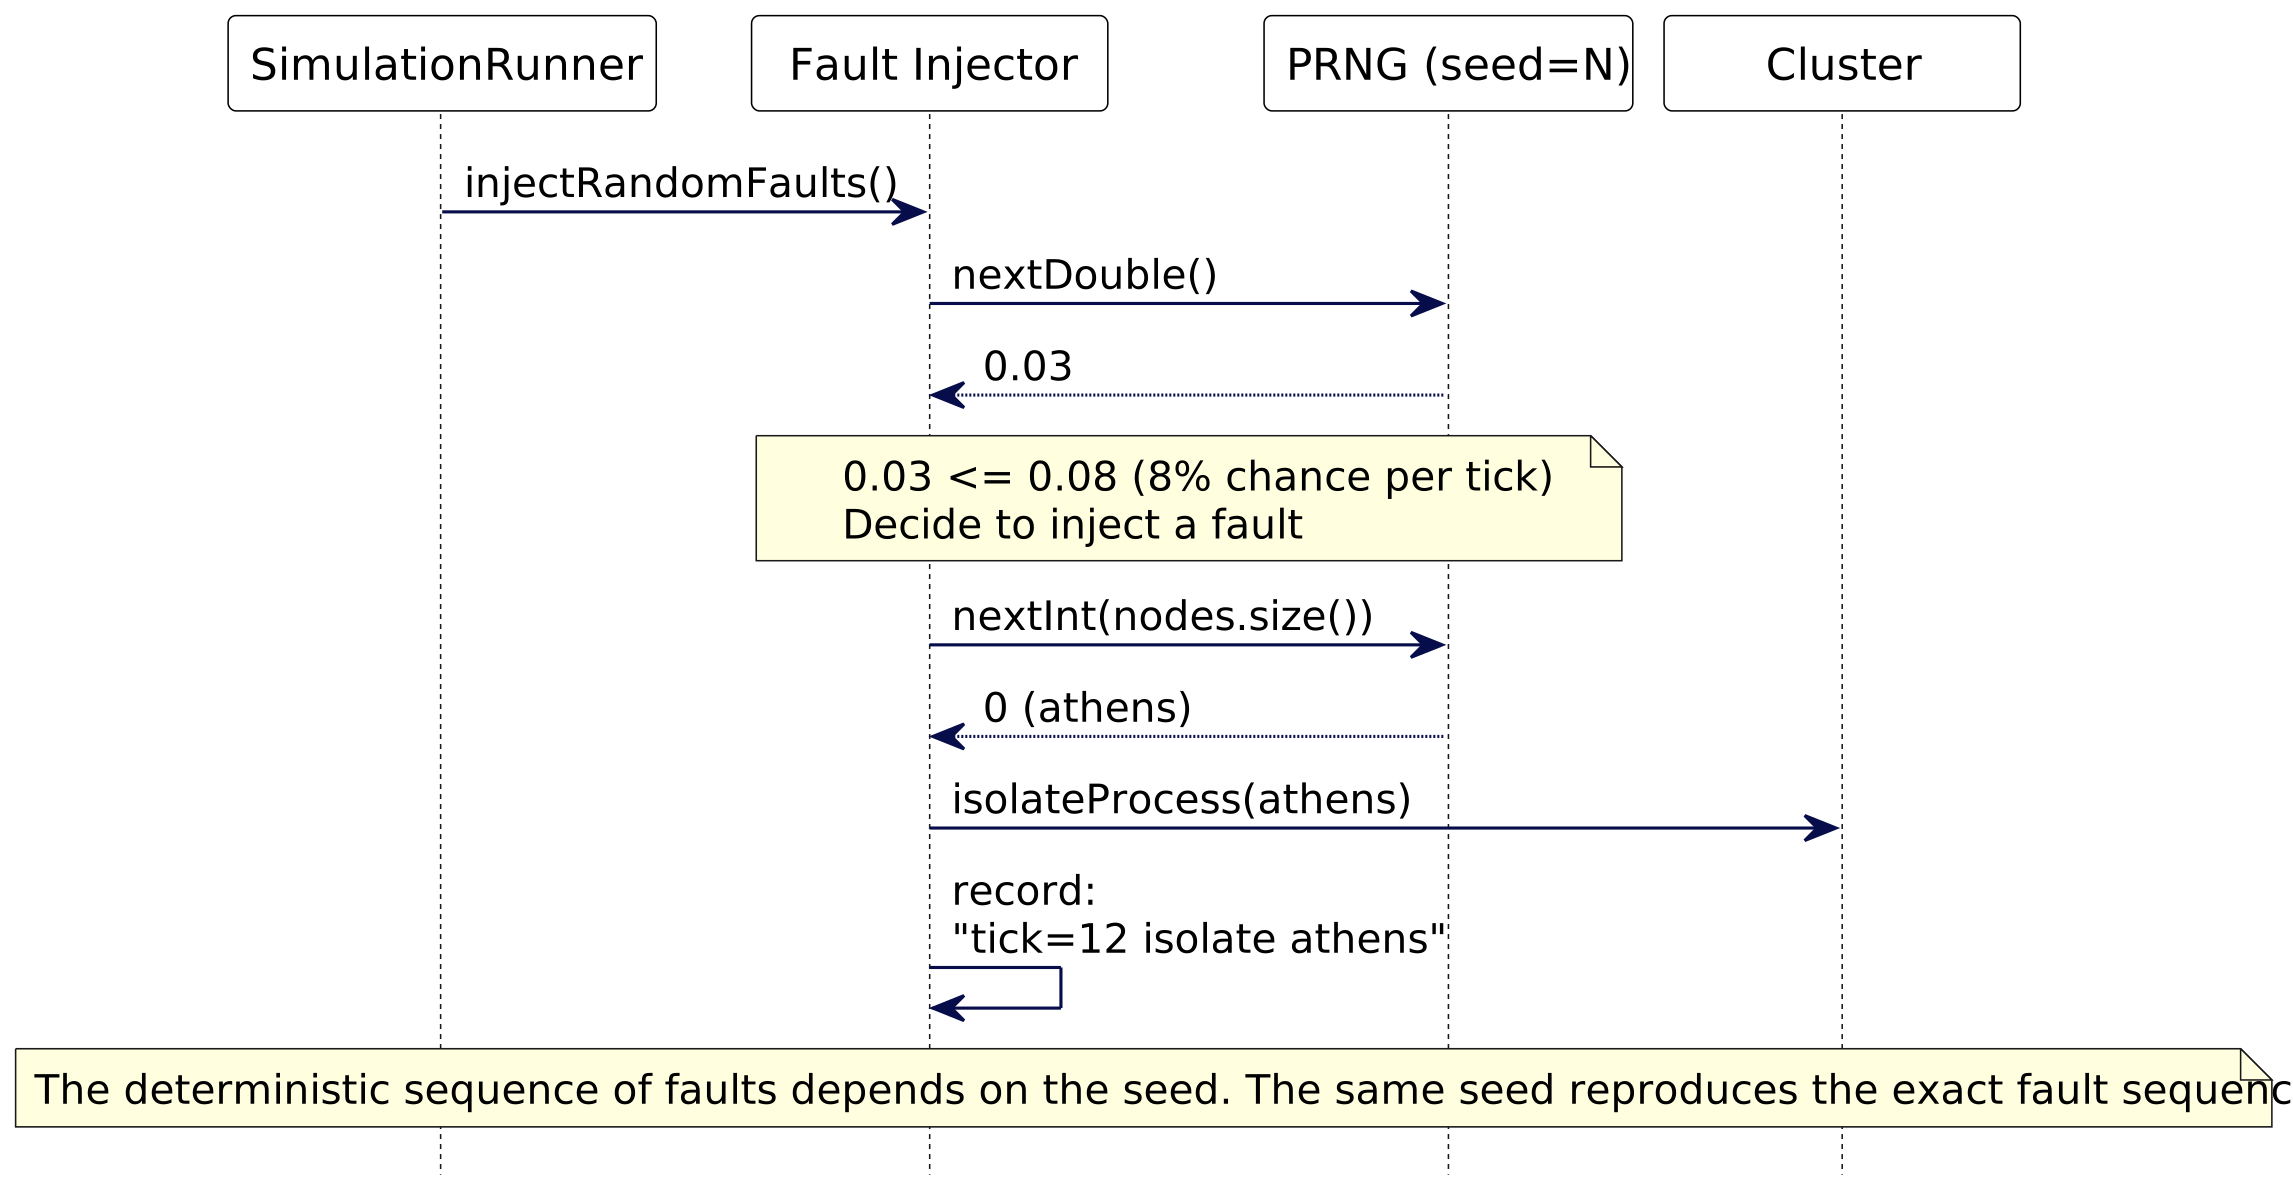
Figure 15: At each tick, the runner uses the seeded PRNG to decide whether to inject a fault and pick which node to isolate.
The example implementation uses a common utility, a SimulationDecisions to have a central place,
where we make decisions. Whether to issue a client request or introduce
a fault are made by picking a value from random.nextDouble()
and comparing it with a configured probability threshold.
It also provides helper methods to pick fault types, select target
nodes, choose delay durations, and trigger periodic network healing:
class SimulationDecisions
      public static final double DEFAULT_REQUEST_PROBABILITY = 0.4;
      public static final double DEFAULT_FAULT_PROBABILITY = 0.08;
      public static final int DEFAULT_HEAL_INTERVAL_TICKS = 40;

      private final Random random;
      private final double requestProbability;
      private final double faultProbability;
      private final int healIntervalTicks;

      public SimulationDecisions(Random random) {
          this(random, DEFAULT_REQUEST_PROBABILITY, DEFAULT_FAULT_PROBABILITY, DEFAULT_HEAL_INTERVAL_TICKS);
      }


      public boolean shouldIssueClientRequest() {
          return random.nextDouble() <= requestProbability;
      }

      public boolean shouldInjectFault() {
          return random.nextDouble() <= faultProbability;
      }

      public boolean shouldHealNetwork(long currentTick) {
          return currentTick % healIntervalTicks == 0;
      }

      public FaultType chooseFaultType() {
          FaultType[] types = FaultType.values();
          return types[random.nextInt(types.length)];
      }
The SimulationRunner initializes SimulationDecisions
with a random number generator with a seed.
class SimulationRunner
  protected final SimulationDecisions simulationDecisions;

  public SimulationRunner(long randomSeed, int clusterSize, int numClients,
                          ProcessFactory processFactory,
                          Cluster.ClientFactory<QuorumReplicaClient> clientFactory) throws IOException {
      Random random = new Random(randomSeed);
      this.simulationDecisions = new SimulationDecisions(random);
      this.cluster = Cluster.createSimulated(clusterSize, processFactory, random);
      this.clients = createClients(numClients, clientFactory);
  }

  private void runClusterFor(long runForTicks) {
      for (int i = 0; i < runForTicks; i++) {
          currentTick++;
          injectRandomFaults();
          cluster.tick();
          maybeIssueClientRequest();
      }
  }

  private void maybeIssueClientRequest() {
      if (simulationDecisions.shouldIssueClientRequest()) {
          // A client is single-threaded and issues one request at a time.
          // If a request is pending, the request is buffered and issued later.
          SingleRequestIssuer<ClusterClient> client = simulationDecisions.pick(clients);
          client.issueRequest();
      }
  }
The faults like isolate a random node, partition a random pair, delay a random directed link, or drop all messages are then injected randomly.
class FaultInjectingSimulationRunner
  @Override
  protected void injectRandomFaults() {
      if (simulationDecisions.shouldHealNetwork(currentTick())) {
          cluster().resetNetworkConditions();
          faultSchedule.add("tick=" + currentTick() + " heal-all");
          return;
      }

      if (!simulationDecisions.shouldInjectFault()) {
          return;
      }

      SimulationDecisions.FaultType fault = simulationDecisions.chooseFaultType();
      switch (fault) {
          case ISOLATE_NODE   -> isolateRandomNode();
          case PARTITION_PAIR -> partitionRandomPair();
          case DELAY_LINK     -> delayRandomDirectedLink();
          case DROP_LINK      -> dropRandomDirectedLink();
      }
  }
The same seed produces the same sequence of faults, and the same sequence of faults produces the same client visible results. If a bug shows up for seed 42, running seed 42 again reproduces it.
Alongside replaying with the seed, logging both the injected faults
(such as tick=12 isolate athens or
tick=23 delay athens->byzantium by 5) and the
process and network events at each tick makes failures much easier to
diagnose. Often, examining the combined fault schedule and execution
log is enough to spot the exact message interleaving that caused the
violation without even rerunning the simulation in a debugger—and
these structured, tick-stamped logs are particularly effective when
handed to an LLM to analyze what went wrong.
Fast-Forward Execution
In production, every tick represents a fixed amount of real time. If
whoever invokes ticks has 10ms elapsed time between tick calls, a
timeout of 10 ticks expires after 100ms. Systems like
TigerBeetle
fix this interval to 10ms (tick_ms = 10), while etcd
typically uses a 100ms ticker with a 10-tick (one second) election
timeout.
A cluster under test has to run for the time duration it is testing. To see a one-second timeout fire, a live test waits one real second. Every delayed message, retry and recovery adds more. Fault testing explores combinations of delays, faults and requests, and thousands of possible runs quickly add up to days of real clock time.
The simulation advances tick by tick. So it does not need to wait for real time to elapse. The protocol still waits for 100 ticks, but those 100 ticks are 100 iterations of the driver loop running the cluster. Each iteration injects any faults for that tick, ticks the cluster, and may issue a new client request. The loop runs as fast as the CPU can execute it, so a run that would take hours on a live cluster takes seconds.
Replay helps after a bug is found. Fast-forward helps find it in the first place. Rare combinations of delays, failures, retries and timeouts come up because the simulation can try so many possible variations.
Correctness Checking
A common approach to check if the cluster behaved as expected, is to produce a client-visible history: the sequence of invocations and completions that clients observed. This history can be fed into correctness checkers.
The approach used by
Jepsen is to record client operations and their results
in EDN format. Each client operation produces an :invoke
event, followed by an :ok, :fail, or
timeout:
[
  {:process 0, :type :invoke, :f :write, :value ["Key-1" "Value-1"]}
  {:process 0, :type :ok,     :f :write, :value ["Key-1" "Value-1"]}
  {:process 1, :type :invoke, :f :read,  :value ["Key-1" nil]}
  {:process 1, :type :ok,     :f :read,  :value ["Key-1" "Value-1"]}
  {:process 2, :type :invoke, :f :write, :value ["Key-2" "Value-2"]}
  {:process 2, :type :fail,   :f :write, :value ["Key-2" "Value-2"]}
]
After a run, the SimulationRunner passes the recorded
history to a ConsistencyChecker, which checks whether
it is linearizable for a register:
class FaultInjectingSimulationRunnerTest
  @Test
  void faultInjectedHistoryShouldBeCheckable() throws IOException {
      long seed = 123L;
      long runForTicks = 500;
      var runner = new FaultInjectingQuorumKVScenarioRunner(seed);
      History history = runner.runAndGetHistory(runForTicks);

      assertFalse(runner.faultSchedule().isEmpty(), "Expected at least one injected fault");
      assertTrue(ConsistencyChecker.check(history, LINEARIZABILITY, REGISTER));
  }
If the checker finds a violation, the seed that produced it is enough to reproduce the exact execution. There is no need to guess at timing or hope for the right interleaving. The developer can step through the exact tick sequence that led to the bug.
Simulating the File System
The storage layer can cause issues when crashes happen abruptly,
before data in the operating system's page cache and storage buffers
is durable. Operating systems provide separate APIs like
fsync to guarantee that data is persisted onto the
storage media, but there are tricky error
scenarios when an fsync call fails. This is one
reason many modern storage systems use O_DIRECT to
bypass the operating system's page cache and read and write directly
to the storage device. File system simulation can be implemented in a
way similar to the network: storage code talks to files through an
asynchronous interface, FileIO.
public interface FileIO {

    TickCompletableFuture<ByteBuffer> read(long offset, int length);

    TickCompletableFuture<Integer> write(ByteBuffer buffer, long offset);

    TickCompletableFuture<Void> sync();

    TickCompletableFuture<Long> size();

    TickCompletableFuture<Void> truncate(long newSize);

    TickCompletableFuture<Void> close();
}
Every operation returns a future instead of blocking the main thread.
A completed write() only means the bytes are visible to
later reads. Only a completed sync() guarantees that
previous writes are durable across a crash.
There are two implementations of FileIO:
- In tests:
SimulatedFileIOoperates on an in-memorySimulatedFileand advances queued operations ontick(). - In production:
SingleThreadedFileIOexecutesFileChannelcalls on a dedicated background I/O thread and delivers completions back to the main thread duringtick().
The core difference between written data and durable data can simply be
represented by two byte arrays.
SimulatedFile represents a file as two byte arrays in
memory: visible holds bytes written so far including
unsynced writes, and durable holds bytes that have been
synced. Reads and writes use visible. Calling
sync() copies visible to
durable. A crash discards unsynced writes by resetting
visible back to durable, allowing storage
components like a Write-Ahead Log to be
tested deterministically across crashes and restarts.
final class SimulatedFile {
    private byte[] visible = new byte[0];
    private byte[] durable = new byte[0];

    long size() {
        return visible.length;
    }

    byte[] read(long offset, int length) {
        if (offset >= visible.length) {
            return new byte[0];
        }
        int from = (int) offset;
        return Arrays.copyOfRange(visible, from, Math.min(visible.length, from + length));
    }

    void write(long offset, byte[] data) {
        long end = offset + data.length;
        if (end > visible.length) {
            visible = Arrays.copyOf(visible, (int) end);
        }
        System.arraycopy(data, 0, visible, (int) offset, data.length);
    }

    void truncate(long newSize) {
        if (newSize < visible.length) {
            visible = Arrays.copyOf(visible, (int) newSize);
        }
    }

    void sync() {
        durable = visible.clone();
    }

    /** On restart, what is on disk is what becomes visible. */
    void crash() {
        visible = durable.clone();
    }
}
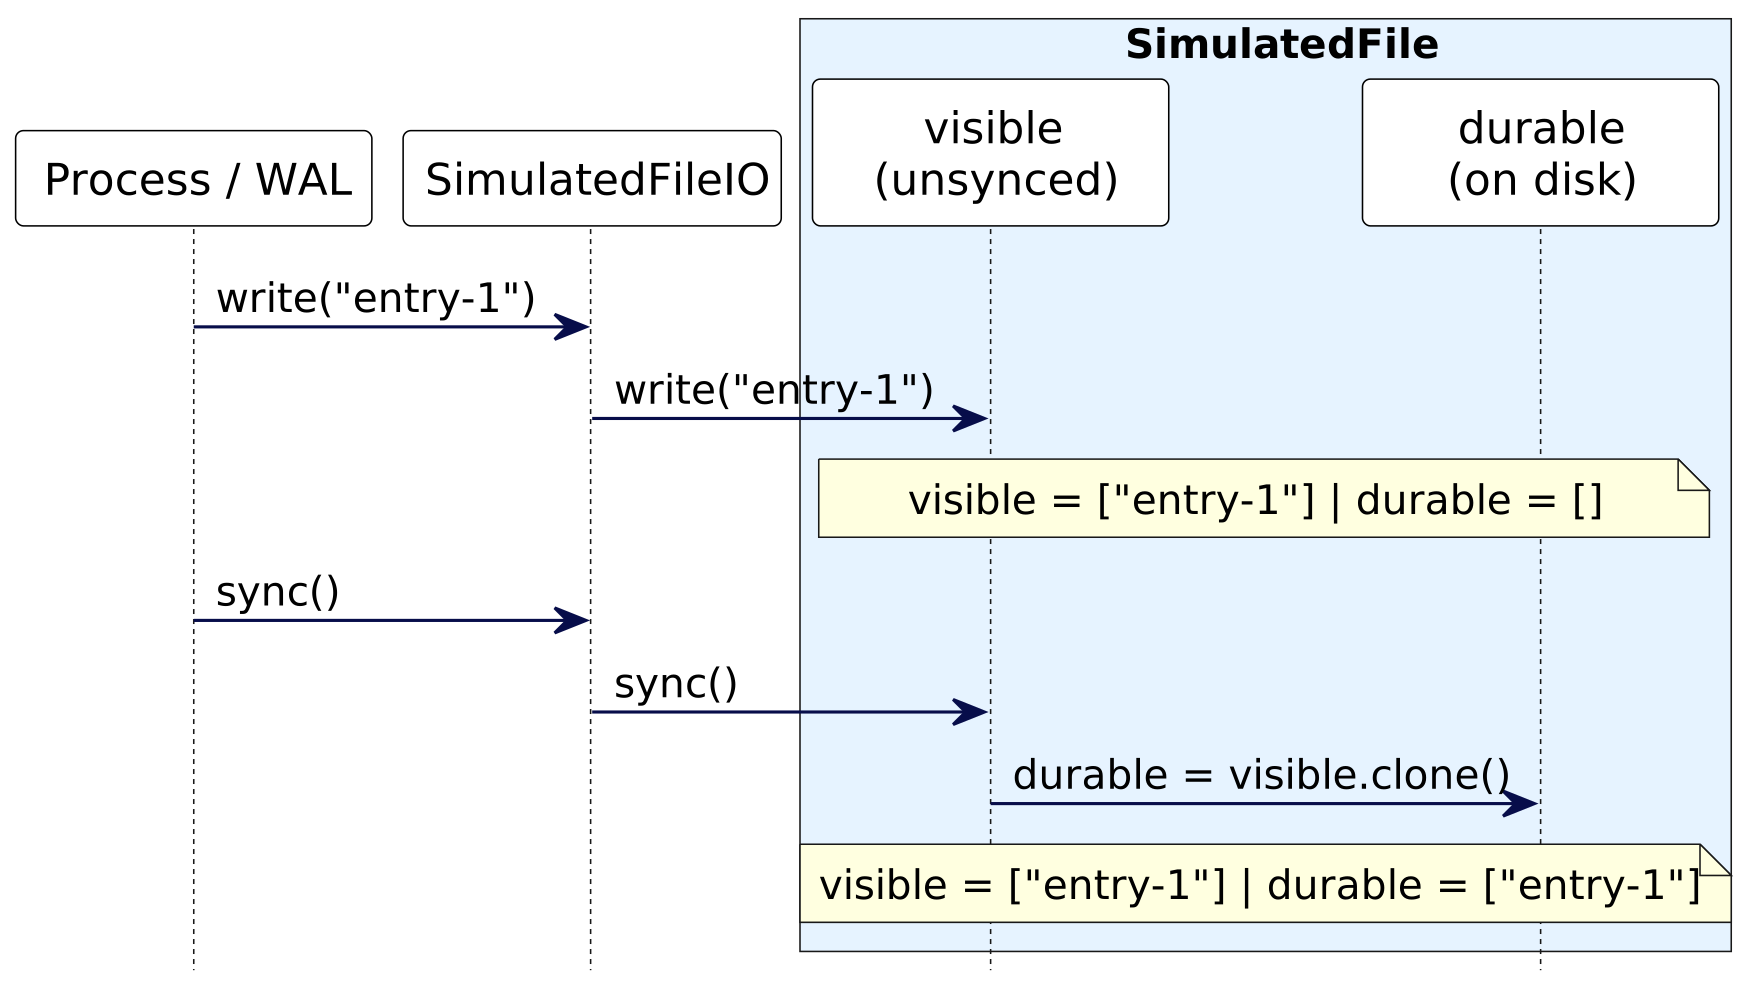
Figure 16:
Writing updates visible; calling sync()
copies visible to durable.
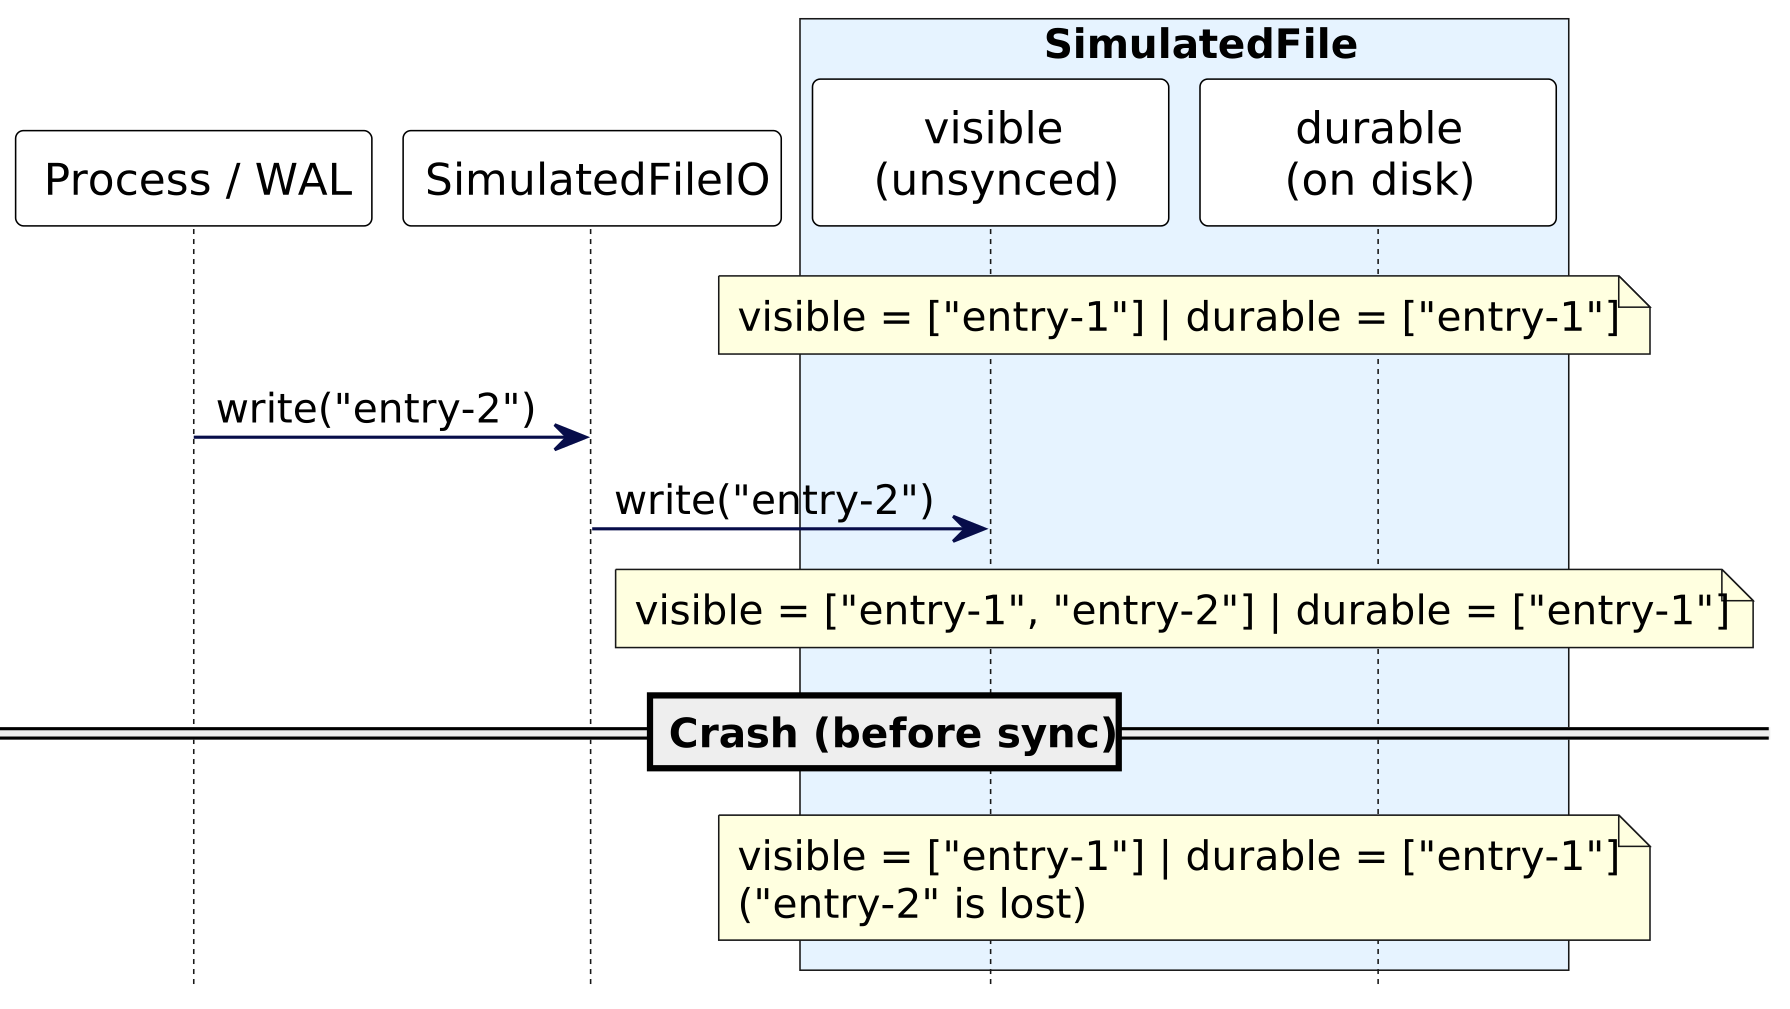
Figure 17:
A crash before sync() resets visible back
to durable, losing unsynced writes.
To fulfill the async contract of FileIO,
SimulatedFileIO wraps SimulatedIO.
Operations like
read() and write() submit their work to a
queue and return a future:
class SimulatedFileIO
  @Override
  public TickCompletableFuture<ByteBuffer> read(long offset, int length) {
      return submit(() -> ByteBuffer.wrap(file.read(offset, length)));
  }

  @Override
  public TickCompletableFuture<Integer> write(ByteBuffer buffer, long offset) {
      // Copy now: the write takes effect later, and the caller may reuse its buffer.
      byte[] data = new byte[buffer.remaining()];
      buffer.duplicate().get(data);
      return submit(() -> {
          file.write(offset, data);
          return data.length;
      });
  }
An explicit tick() call executes the queued operations on
SimulatedFile and completes their futures:
class SimulatedFileIO
  @Override
  public void tick() {
      // Only the calls queued before this tick: a call made from a callback completes on the next tick.
      for (int due = queue.size(); due > 0; due--) {
          queue.poll().run();
      }
  }
Non-Blocking Futures
One thing to notice is the use of custom Future implementation in this API.
It is convenient to have a Future abstraction for composing async
operations. But standard futures like Java's
CompletableFuture are risky in a single-threaded event
loop for two reasons. Blocking methods like get() or
join() would freeze the main thread and prevent the tick
loop from ever completing the operation. And asynchronous combinators
like thenApplyAsync() dispatch callbacks onto background
thread pools, reintroducing thread-scheduling nondeterminism and race
conditions on replica state.
TickCompletableFuture
avoids both by not exposing any blocking calls. It has no background
executors and allows attaching callbacks to compose async operations.
Trade-offs
Deterministic simulation testing cannot be added as an afterthought; it requires upfront architectural investment. As the need for a custom future illustrates, high-level design choices—a single-threaded core, asynchronous I/O interfaces, and avoiding thread-heavy libraries—are critical and have to be built into the system from the start.
Crucially, these constraints apply only on the deterministic side of an
architectural seam. Interfaces like Network,
FileSystem, FileIO, and Clock
form the boundary between the simulated core and the operating system.
Behind that seam, production implementations such as
NioNetwork,
SingleThreadedFileIO,
and SystemClock are free to use background I/O threads,
ExecutorService, NIO socket channels, and system clocks—as
long as they deliver their results back onto the single-threaded
tick() loop.
Strict Coding Rules
To keep the core deterministic and the seam intact, the code must follow six strict coding rules:
- No system clock calls:
Time must come from the simulated
Clockor tick counter. Nothing likeSystem.currentTimeMillis(),System.nanoTime(), orInstant.now()can be directly used. - No unseeded randomness:
All random decisions or IDs should come from the provided
seeded
RandomGeneratororIdGen. - No threads or standard futures:
The code should not directly use
Thread,Executor, orCompletableFuture. - No direct network or disk I/O:
All I/O must go through the
NetworkandFileIOinterfaces. - No iteration over unordered collections:
While key lookups on a
HashMaporMap.of()are deterministic, iterating overHashMap,HashSet, orConcurrentHashMap(for example, whenRequestWaitingListscans pending requests to expire timeouts) can visit entries in a different order across runs. To prevent accidental iteration over these unordered collections, core state usesLinkedHashMapandLinkedHashSet, which guarantee insertion-order iteration. - No cross-thread callbacks across the seam: Background threads
in production adapters must never directly invoke methods or
complete futures on the deterministic side. In
IOThread, for example, the disk thread never callsfuture.complete()itself—doing so would execute storage and replica callbacks on the I/O thread, introducing data races in production that never happen in simulation. Instead, it queues completions for the main thread to drain duringtick().
Because even a single usage of HashMap or
System.currentTimeMillis() inside a message handler will
silently break the replayability guarantee
when a rare fault sequence hits that code path later—relying on developer
discipline or code reviews to enforce these rules does not scale.
Instead, we can guard the system using automated
architectural fitness functions:
- Static fitness functions with ArchUnit: Using a tool like
ArchUnit, a
DeterminismRulesTestsuite runs on every build as an atomic, static fitness function to verify that core protocol and storage packages stay behind the architectural seam and obey the first five determinism rules. - Runtime thread-confinement checks in code: Static bytecode
analysis like ArchUnit cannot tell which thread executes a lambda at
runtime—it cannot distinguish
IOThreadcallingfuture.complete()on a background thread from queueing it fortick(). The sixth rule therefore has to be enforced in the code itself:TickCompletableFuturecaptures the thread that created it and rejectscomplete(),fail(), orwhenComplete()calls from any other thread:class TickCompletableFuture
private final Thread ownerThread = Thread.currentThread(); private void checkOnOwnerThread() { if (Thread.currentThread() != ownerThread) { throw new IllegalStateException( "TickCompletableFuture must be accessed on its owner (tick) thread [" + ownerThread.getName() + "], but was called from [" + Thread.currentThread().getName() + "]"); } } public void complete(T result) { checkOnOwnerThread(); if (state != State.PENDING) { throw new IllegalStateException("Future is already resolved"); } this.state = State.COMPLETED; this.result = result; if (callback != null) { callback.accept(result, null); callback = null; } } - A holistic fitness function for distributed correctness: Once
the static rules and runtime thread checks guarantee deterministic
execution, the seeded
FaultInjectingSimulationRunnerandConsistencyCheckeract as a holistic fitness function that verifies system-wide invariants like linearizability and crash durability across numerous fault sequences.
Production Cost
A natural question is whether designing for single-threaded simulation hurts production performance or resource usage. In practice, the opposite is often true. Most of the distributed systems are often IO bound. So single-threaded processing with asynchronous, batched I/O actually works better, eliminating locking and thread context-switching. This is the same architecture used for high throughput and low latency systems like Redis, FoundationDB, and TigerBeetle.
The trade-off is that handlers on the tick()
thread must never block or perform long-running CPU work, which would
stall message processing. Because a single event
loop uses one CPU core for protocol logic, scaling across a multi-core
machine is done by running multiple independent processes rather than sharing mutable state across
a large thread pool.
Ease of Building and Evolving
In my experience, while building the simulation foundation takes
upfront effort, it makes the core protocol logic easier to write and
evolve. Separating the core from network sockets, threads, and clock
time makes it easier to reason about. As seen in
QuorumReplica, the handlers are plain single-threaded
code.
The biggest benefit is the convenience of exploring random fault combinations. Evolving the system becomes much safer and easier, as the fault scenario tests act as a fitness function.
Learning and the Use of LLMs
An excellent side effect is using this technique for learning and teaching distributed systems. Once foundational code like Tickloom is in place, those abstractions provide a harness that allows using LLMs as a natural-language interface to build and explore systems.
While reading a book, documentation, or an engineering article, we
often need to work through tricky corner-case scenarios that are
usually only sketched as diagrams on a whiteboard. With a
deterministic simulation harness in place, we can ask an LLM to
generate executable scenario tests and explore working code directly.
For example, while reading the quorum linearizability anomaly in
Designing Data-Intensive Applications,
an LLM can translate the book's diagram directly into an executable
Tickloom scenario like
DDIA_LinearizabilityScenarioTest,
where link delays and partitions cause one client to read a new value
and a subsequent client to read a stale one. It becomes much easier to
deep-dive and learn with this kind of executable codebase to explore.
Acknowledgments
I would like to thank Martin Fowler, Rebecca Parsons, Will Wilson, and Joran Dirk Greef for reviewing drafts of this article and for their valuable feedback and suggestions.
Significant Revisions
17 November 2026: published